InferenceQL - AI for Data Engineers, Without the Math
Explore AI-powered data analysis with InferenceQL, an open-source platform enabling data engineers to build and query models using SQL-like syntax and intuitive interfaces, without requiring advanced mathematical knowledge.
Flare - Optimizing Apache Spark for Scale-Up Architectures and Medium-Size Data
Optimizing Apache Spark for medium-size data on single powerful servers. Flare accelerator module delivers significant speedups using code generation techniques inspired by main-memory database systems.
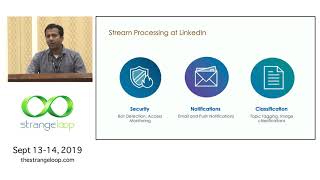
Riding the Stream Processing Wave
Explore LinkedIn's stream processing challenges, innovations in machine learning applications, and advancements in nearline processing. Learn about state management and offline-online convergence in large-scale data systems.
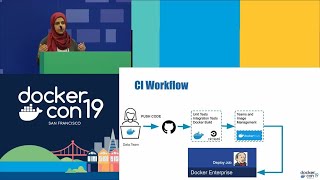
Data Tells Us You Will Love This Talk
Explore Docker's data engineering infrastructure, insights delivery, and best practices for creating a data-centric culture within the company.
NuGraph - GraphDB as a Cloud Service Built Upon JanusGraph and FoundationDB
Explore eBay's NuGraph, a high-performance GraphDB cloud service built on JanusGraph and FoundationDB, designed for secure, real-time business insights from massive datasets.
The JanusGraph FoundationDB Storage Adapter
Explore JanusGraph's new FoundationDB storage adapter, adding distributed ACID support. Learn about property graph models, read/write patterns, and how FoundationDB addresses JanusGraph challenges.
Intelligent OT-Data Pipelines - Machines to Clouds
Explore Project Fledge's architecture for handling OT data's unique requirements, enabling automated factories and distributed edge applications from machine to cloud.
Building a Unified Cancer Immunotherapy Data Library
Explore a unified cancer immunotherapy data library leveraging Datomic for efficient storage, querying, and collaboration. Learn about CANDEL's innovative approach to managing complex research data.
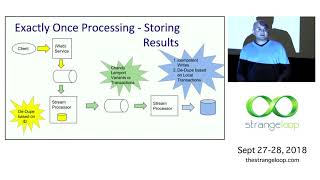
Chasing the Stream Processing Utopia
Explore stream processing challenges and solutions at internet scale, covering event ingestion, real-time data processing, and performance optimization techniques for large-scale applications.
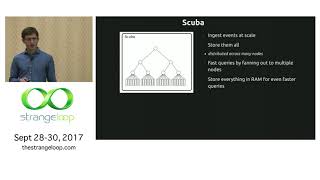
Why We Built Our Own Distributed Column Store
Explore the architecture and implementation of Retriever, a custom-built distributed column store database inspired by Facebook's Scuba, designed for efficient querying of large-scale event data.
DataDevOps for the Modern Data Warehouse on Microsoft Azure
Explore DevOps principles for Big Data Analytical Pipelines using Azure Data Platform, including Data Factory, Databricks, and Data Lake Gen2. Learn to build and operationalize multi-source Modern Data Warehouses.
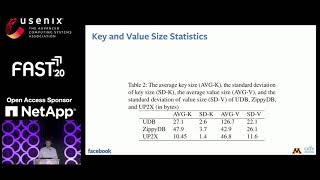
Characterizing, Modeling, and Benchmarking RocksDB Key-Value Workloads at Facebook
Detailed analysis of RocksDB workloads at Facebook, revealing key-value usage patterns and proposing improved benchmarking methods for more accurate representation of real-world scenarios.
Operating Elasticsearch with Ease at Scale
Discover strategies for operating Elasticsearch at scale, covering common issues, optimization techniques, and best practices for handling massive deployments with billions of ingests and millions of searches daily.
Can You Roll Your Own SIEM
Explore building a custom cloud-native SIEM solution, discussing considerations, requirements, and benefits compared to vendor options. Learn about cost savings and improved capabilities.
An Offensive Approach to Analyzing Huge and Complex Big Data Infrastructures
Explore attack vectors in Big Data stack layers: ingestion, storage, processing, and access. Learn methodologies to identify vulnerabilities in complex infrastructures handling massive data volumes.
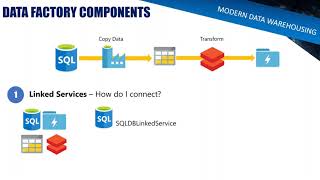
From ETL to Data Engineering with Azure Data Factory
Explore modern Azure Data Factory features for efficient, scalable data pipelines. Learn parameterization, dynamic workflows, and integration with Azure Databricks for cloud-native ETL solutions.
Productionizing Data Platform Best Practices - Self Service
Explore best practices for implementing self-service capabilities in data platforms, enhancing efficiency and empowering users to access and utilize data effectively.
Processing Fast Data with Apache Spark - The Tale of Two Streaming APIs
Explore Apache Spark's streaming APIs for fast data processing, comparing Spark Streaming and Structured Streaming through practical examples and guidance on implementation.
Why Most Data Projects Fail and How to Avoid It
Explore common reasons for data project failures and learn strategies to ensure success by addressing key aspects like team composition, value creation, timelines, architecture, and execution planning.
Where Does the Real World End - The Blurring of the Physical and Digital
Exploring the convergence of physical and digital realms through IoT, sensors, and computing advancements, examining implications for business, society, and emerging applications.
Mnemosyne - A Distributed Bitmapped Indexing Layer for Big Data
Explore building a distributed indexing layer for big data, covering design principles, data ingestion, storage, modeling, and in-memory computing techniques for scalable, real-time querying.