Workflows of Highly Functional App and Data Engineering Teams
Explore enterprise data engineering principles: schema management, standards enforcement, testing, and automated deployment. Learn strategies for handling change, observability, and quality at scale.
Database Native Support for CDC Streaming Pipeline
Explore a database-native solution for Cassandra's CDC logs, addressing common challenges and proposing an improved architecture based on industry insights and managed CDC solutions.
Tales at Scale - Analytics at 1000 QPS and Beyond
Explore high-performance analytics techniques for handling 1000+ queries per second, covering Apache Druid, CPU/IO optimization, and scaling strategies for heterogeneous workloads.
Leveraging Open-Source Tools for Building a Quality Data Warehouse
Discover how to build a quality data warehouse using open-source tools. Learn about modern data stack architecture, test-driven approaches, and software development best practices for data transformation.
Building a Data Science Program in Higher Vocational Education
Explore a two-year data science program designed for higher vocational education, featuring industry-aligned courses and modern educational approaches like Discord communities and GitHub portfolios.
Challenges and Learnings of Machine Learning at Scale
Explore challenges and learnings of training millions of models efficiently, optimizing costs, and achieving high-performance daily predictions in machine learning.
Building an Open Data Lakehouse Using Apache Spark, Apache Iceberg and Dremio
Explore the evolution of big data to data lakehouses, focusing on open architecture development, security, governance, and augmentation using Dremio, Apache Spark, and Apache Iceberg.
Power Query in 20 Minutes - How it Works
Explore Power Query's internals and gain a deeper understanding of this increasingly prevalent tool in Power BI and Fabric technologies.
Generate Test Data Quick, Easy and in Large Volumes with the Databricks Labs Data Generator
Generate terabytes of proper test data quickly and easily using Databricks Labs Data Generator for dev environments across Azure, AWS, and GCP.
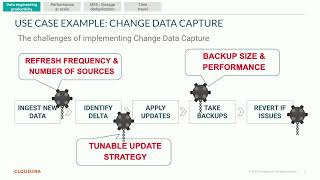
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.
New Features of Apache NiFi - Tips and Techniques
Explore Apache NiFi's latest features, processors, and best practices. Build efficient data flows using cutting-edge techniques, with tips and guides for optimal implementation.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
The Free Lunch is Over: Dealing with Unstructured Data in the Era of LLMs
Explore unstructured data processing using ML, LLMs, and Apache tools. Learn to handle audio, images, and text with vector embeddings for natural language analysis in data engineering pipelines.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Domain Knowledge Augmented AI for Databases - Alibaba
Explore domain knowledge augmented AI for databases, focusing on Alibaba's innovative approaches and their impact on database management systems.
Machine Learning with Apache Beam
Explore Apache Beam for distributed data pipelines in machine learning, covering inference, data processing, and training with hands-on demos for parallelizing ML workloads.

Ensuring Data Quality in Databricks with Great Expectations
Integrate Great Expectations with Databricks to set, test, and enforce data pipeline expectations, ensuring accuracy and reliability in your data workflows.

Delta Format and Live Tables - Pioneering Data Innovation
Explore Delta format and Live tables, understanding their role in scalable big data pipelines and modern data engineering innovations.

Data Engineering: A Deep Dive into Databricks
Master Databricks for efficient data processing, focusing on Apache Spark transformations, ingestion methods, storage, orchestration, and best practices to optimize data engineering workflows.

ETL Observability: Azure to Snowflake - Monitoring with Splunk and Power BI
Explore ETL monitoring from Azure to Snowflake using ADF, Splunk, and Power BI. Learn data lineage and observability techniques for efficient pipeline management.

Data Engineering with Databricks - Leveraging the Lakehouse Platform for ETL Pipelines
Leverage Databricks Lakehouse Platform to build ETL pipelines, use Delta Live Tables, and orchestrate tasks with Workflows for efficient data processing.