How to Build a Cloud Data Platform - Machine Learning and Business Intelligence - Part 4
Learn to leverage Delta Lake for dashboards and advanced analytics, enabling downstream teams with machine learning and business intelligence capabilities on a unified data platform.
Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
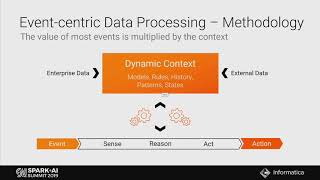
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
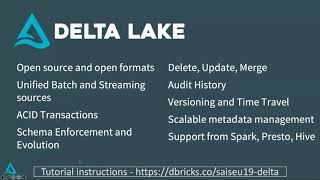
Building Data Intensive Analytic Applications on Top of Delta Lakes
Explore Delta Lake's ACID transactions for Apache Spark, enhancing data reliability and query performance. Learn to address challenges in modern data engineering through hands-on examples and practical applications.
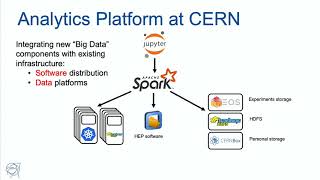
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
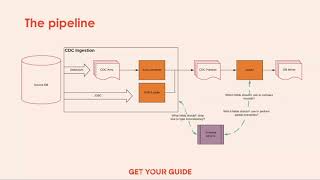
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.
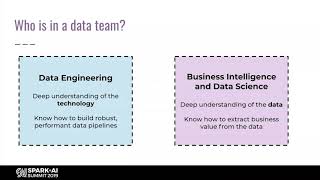
Best Practices for Building and Deploying Data Pipelines in Apache Spark
Learn best practices for building and deploying efficient, reproducible data pipelines in Apache Spark. Discover a toolkit that simplifies pipeline creation for non-engineers and explore deployment strategies.
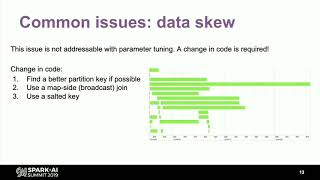
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
Different Streaming Methods with Apache Spark and Kafka
Explore real-time analytics using Apache Spark and Kafka. Learn about streaming methods, overcoming technical challenges, and innovative solutions for handling billions of daily events in a scalable, cost-efficient manner.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
Building a Lakehouse Architecture for Business Data Empowerment
Explore building a data platform using LakeHouse Architecture, focusing on data curation, GDPR compliance, and open-source technologies to empower businesses with reliable, timely, and accessible data.
Orchestration Made Easy with Databricks Workflows
Discover Databricks Workflows: a managed orchestration service for streamlined data pipelines. Learn to create, run, and monitor reliable workflows, implement recovery actions, and explore new features for efficient data management.
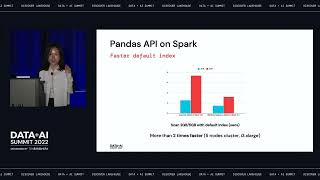
PySpark in Apache Spark 3.3 and Beyond
Explore PySpark's evolution in Apache Spark 3.3, including improved Pandas API, enhanced productivity features, and future developments. Learn about new functionalities, usability improvements, and performance enhancements.
Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.
Data-Centricity - A Challenge and Opportunity for CS Education, by Shriram Krishnamurthi
Exploring data-centric approaches in computing education, emphasizing curricular innovations at university and school levels to adapt to the data-driven landscape of modern computing.
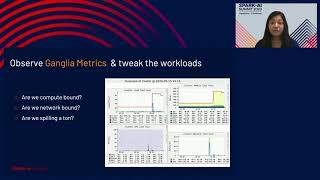
Best Practices for Building Robust Data Platforms with Apache Spark and Delta
Learn best practices for building robust data platforms using Apache Spark and Delta. Gain insights on optimizing performance, scaling, security, and cost-effectiveness in big data architectures from real-world experiences.
Patterns and Operational Insights for Large-Scale Delta Lake Workloads
Explore effective Delta Lake patterns, optimization techniques, and operational insights for managing large-scale data workloads on Databricks, including streaming ETL, data enrichment, and analytics.
Delta Lake 0.7.0 and Spark 3.0 - Ask Me Anything Session
Illuminating AMA session with Apache Spark and Delta Lake experts. Explore Spark 3.0 and Delta Lake's latest features, use cases, and development insights. Perfect for data engineers seeking cutting-edge knowledge.
Healthcare Claim Reimbursement Using Apache Spark - Optum's System Transformation
Optimizing healthcare claim processing with Apache Spark: Improved performance, reduced costs, and enhanced capabilities for hospitals' revenue recovery through efficient data processing and analysis.
Scaling Data and ML with Apache Spark and Feast - Feature Engineering for Production
Explore scaling data and ML with Apache Spark and Feast, focusing on feature engineering challenges and solutions for big data-driven machine learning in production environments.
Geospatial Data Analysis in Apache Spark - Challenges and Solutions
Explore geospatial data challenges in Apache Spark, comparing libraries, and learning best practices for data ingestion, storage, and retrieval using spatial indexing techniques.