Building an Integrated Data Asset Platform with Apache DolphinScheduler - DataOps Track
Discover how Apache DolphinScheduler powers Unicom Digital Technology's integrated data asset platform, exploring key features and implementation strategies for efficient data operations.
Simplifying Iceberg Table Lifecycle Management - A Comprehensive Approach
Discover efficient strategies for managing Iceberg tables through lifecycle optimization techniques, focusing on Apache Hive and Flink integration for enhanced data warehouse operations.
Row-level Modifications at Petabyte-scale via Impala on Iceberg
Discover how to perform efficient row-level modifications on massive datasets using Impala with Apache Iceberg, enabling petabyte-scale data management and manipulation.
A Data-Driven Approach to Productionizing RAG Systems
Discover practical strategies for deploying RAG applications effectively, focusing on data-driven methods and optimization techniques for enhanced performance and reliability.
Experimental KERAS Feature Space for Medical AI Heart Attack Prediction
Dive into advanced feature scaling with KERAS Feature Space, building a medical AI system to predict heart attack probabilities using structured data classification and optimized data pipelines.
How Replit Trained Their Own LLMs - LLM Bootcamp
Comprehensive guide to training custom LLMs: from data processing and tokenization to evaluation and deployment, with insights on tools, best practices, and essential skills for LLM engineers.
A Deep Dive into Kubeflow Pipelines
Explore Kubeflow Pipelines' architecture and components for executing cloud-native ML workflows on Kubernetes. Gain insights into the platform's inner workings and integration of ML pipeline elements.
Product Recommendation System on Kubernetes Using Argo Workflows
Learn to build a product recommendation system using Argo Workflows on Kubernetes. Explore DataOps, pipelines, and tools like Minio and Apache Spark for efficient data processing and analysis.
Leveraging OpenTelemetry for Your Prometheus Pipeline
Explore OpenTelemetry's integration with Prometheus, covering receivers, exporters, migration paths, and common scenarios for leveraging OTel in your metrics pipeline.
Scaling Open Source ML: How Wolt Uses Kubernetes to Deliver Great Food to Millions
Discover how Wolt leverages Kubernetes and open-source frameworks to scale machine learning operations, addressing challenges in forecasting, recommendations, and delivery time predictions for millions of users.
Leveraging Argo Workflows and Argo Events for Cloud Agnostic Enterprise Machine Learning Deployments
Explore implementing Argo Workflows and Events for efficient MLOps, including continuous deployment, model retraining, and best practices for cloud-agnostic machine learning pipelines.
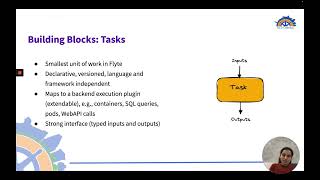
MLOps with Flyte - Challenges and Solutions in Machine Learning Operations
Explore MLOps challenges and solutions using Flyte, an open-source orchestration tool. Learn best practices for efficient ML model development and deployment at scale.
How to Build a Real-Time ML Pipeline for Fraud Prediction
Build a real-time ML pipeline for fraud prediction, addressing challenges in online feature engineering and real-time data ingestion. Learn to generate ML features, use a feature store, and monitor for drift.
Global School Connectivity DataOps Platform
Explore the development of an open-source DataOps stack managing connectivity data for millions of schools, covering ingestion, pipelines, quality, and analytics integration.
Solving Migration Pipelines
Explore strategies for solving migration pipeline challenges in cloud-native environments, focusing on efficiency and scalability.
Build Open Format Data Lakehouse
Explore open format data lakehouse architecture, benefits, and implementation strategies for efficient cloud-native data management and analytics.
DevOps Best Practices for DataOps Mesh
Discover DevOps best practices for implementing DataOps Mesh, enhancing data management and collaboration in complex environments.
Build a Deep Facial Recognition App - Preparing Data for Deep Learning - TF Dataloader
Learn to build a deep facial recognition app using TensorFlow, covering data preparation, image processing, and pipeline creation for training and testing a Siamese Neural Network model.
Predicting Wildfire Hotspots Using California Wildfire Data
Learn to predict wildfire hotspots using California data. Covers data collection, feature engineering, ML modeling with LightGBM/XGBoost/H2O.ai, and visualization techniques for effective wildfire risk assessment.
Democratizing Data Quality Through a Centralized Platform at Zillow
Explore Zillow's centralized platform for data quality, enabling stakeholders to define expectations, perform validations, and monitor data health across complex organizations.

End to End Deep Learning Project Using MLOPS DVC Pipeline With Deployments Azure and AWS - Krish Naik
Comprehensive guide to building and deploying a deep learning project for chicken disease classification using MLOps tools, DVC pipeline, and cloud platforms Azure and AWS.