Running Apache Spark on Kubernetes - Best Practices and Pitfalls
Learn best practices and pitfalls for running Apache Spark on Kubernetes, covering setup, performance optimization, resource management, security, and future developments in this comprehensive overview.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
State of the Industry - Machine Learning Platforms and MLOps
Explore the state of MLOps and ML platforms with industry leaders, focusing on challenges, common components, and Databricks' approach to unified data analytics and machine learning.
Predictive Maintenance on IoT Data for Early Fault Detection with Delta Lake
Explore predictive maintenance using IoT data and Delta Lake for early fault detection. Learn about Industry 4.0 applications, data analytics, and machine learning techniques for improved efficiency and cost savings.
How to Build a Cloud Data Platform - Machine Learning and Business Intelligence - Part 4
Learn to leverage Delta Lake for dashboards and advanced analytics, enabling downstream teams with machine learning and business intelligence capabilities on a unified data platform.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
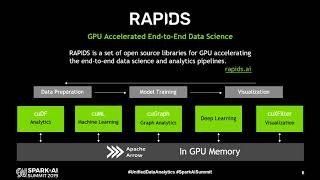
Accelerating Apache Spark with GPUs Using RAPIDS
Explore GPU acceleration for data science with RAPIDS, offering significant performance gains over CPU-only solutions. Learn its functionality, architecture, and integration with Apache Spark for large-scale computation.
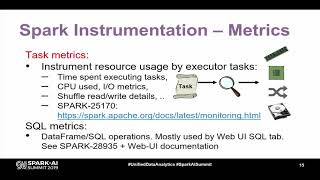
Performance Troubleshooting Using Apache Spark Metrics - Databricks Talk
Explore Apache Spark metrics for performance troubleshooting in distributed data processing. Learn to deploy dashboards, use sparkMeasure, and leverage Spark 3.0 improvements for optimizing workloads.
Level Up Your Game Marketing - Unite Now 2020
Discover best practices for scaling and operating mobile F2P games, focusing on retention, game economies, live service campaigns, and growth metrics in this indie game marketing guide.
The Big Promise of Big Data Analytics - ACM WomENcourage 2020
Explore intelligent data tools bridging users and data. Learn about natural language queries, clarifications, and recommendations for effective data exploration and analysis.
Accelerating Apache Spark Shuffle for Data Analytics on Cloud with Remote Persistent Memory Pools
Innovative solution for accelerating Apache Spark shuffle operations using remote persistent memory pools, improving performance, scalability, and reliability in cloud-based big data analytics.
Adaptive Query Execution: Speeding Up Spark SQL at Runtime
Explore Spark SQL's Adaptive Query Execution framework, which optimizes query plans at runtime using real-time statistics for improved performance in data processing and analysis.
Building the Petcare Data Platform with Delta Lake and Spark ETL Pipeline
Explore Mars Petcare's data platform using Delta Lake and Spark ETL pipeline 'Kyte'. Learn about advantages over Azure Data Factory and leveraging Delta Lake for ETL configurations and data science.
Encryption and Masking for Sensitive Apache Spark Analytics Addressing CCPA and Governance
Practical methods for balancing data encryption and analytics in Apache Spark, addressing CCPA and governance requirements while maintaining analytical value.
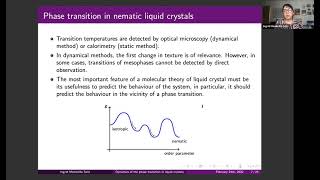
Liquid Crystals Dynamics - What Persistent Homology Reveals
Explore liquid crystal phase transitions through persistent homology, revealing thermodynamic features and structural changes in nanocomposites using advanced data analysis techniques.
Transformations in FMCG Through Data Science
Explore how data science transforms FMCG industry through market evolution, digital manufacturing optimization, and key roadmap development. Gain insights from real-world scenarios and industry experts.
Data Sets for Analytics - What Is a Dataset - Top 25 Datasets
Explore 25 free datasets for analytics, including Iris, Boston, and Titanic. Learn about dataset types, formats, and their importance in machine learning and data analysis.
High-Throughput Spectroscopy and Material Discovery by Beyond-DFT Work and Data-Analysis
Explore high-throughput spectroscopy and materials discovery using advanced computational methods, workflows, and data analysis frameworks for accelerated insights in materials science.
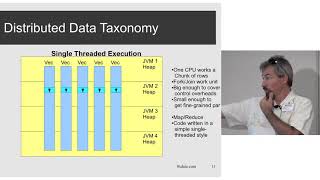
Big Data Analytics and Processing Techniques
Explore big data concepts, distributed systems, and analytics techniques with expert Cliff Click, covering data motion, compression, and efficient processing strategies.
Be Agile and Data-Driven with Azure - Microsoft Ignite Into Focus
Explore Azure's latest capabilities for innovation, mission-critical workload transition, and infrastructure modernization. Learn about Microsoft's Intelligent Data Platform for creating value through integrated data fabric.
Realizing Value Through New Intelligent Capabilities for Microsoft 365 Admins
Discover intelligent features for Microsoft 365 admins to enhance user experiences, gain deeper insights, and proactively address issues while maintaining privacy.