Chiplet-Based Compressed LLC Cache and Memory Expansion for Data Centers
Explore hardware-accelerated chiplet technology for real-time memory compression, enabling cost-effective cache expansion and improved data center performance through innovative architectural solutions.
AI-Driven Memory Solutions for Next-Generation Computing Architecture
Explore cutting-edge memory solutions for AI computing, including CXL-based technologies, computational memory innovations, and evolving software ecosystems for next-generation data processing.
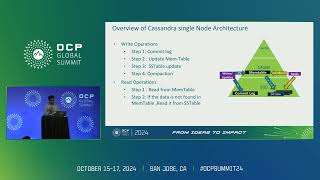
Integrating Composable Memory Solutions into Storage-Intensive Workloads
Explore how CXL memory pooling and expansion techniques optimize performance and reduce TCO for memory-intensive applications like SPARK in data center environments.
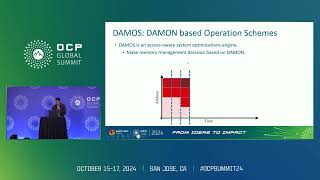
Expanding CXL Software Ecosystem Through HMSDK on Linux
Discover how HMSDK enhances CXL memory management in Linux systems through weighted interleaving, DAMON-based tiering, and heterogeneous memory allocation APIs for optimal performance and capacity expansion.
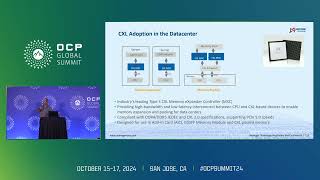
CXL 2.0 Use Case - Using Both DDR4 and DDR5 on the Same Server for Memory and Bandwidth Scaling
Explore CXL 2.0 technology's capabilities for integrating DDR4 and DDR5 memory in data centers, focusing on scalable memory expansion and enhanced bandwidth performance for modern computing needs.
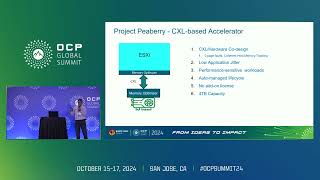
VMware Memory Vision for Real World Applications - Memory Tiering and CXL Implementation
Explore VMware's memory innovation journey, from persistent memory to CXL, discovering real-world applications and benefits for mission-critical databases, AI-ML, and analytics workloads.
Advancing CXL Memory Architecture for Enhanced Performance and Flexible Integration
Explore advanced CXL memory architecture concepts, focusing on performance optimization, integration strategies, and the latest developments in memory system design for modern computing platforms.
Overcoming the GPU Memory Capacity Limitation with Two-Digit Nanosecond Latency CXL Controller
Explore advanced solutions for GPU memory limitations through CXL controller technology, focusing on nanosecond-level latency optimization and enhanced capacity management.
Case for DRAM Translation Layer - It's Like FTL but for CXL DRAM
Explore the innovative DRAM Translation Layer technology and its application in CXL DRAM systems, drawing parallels with Flash Translation Layer for enhanced memory management.
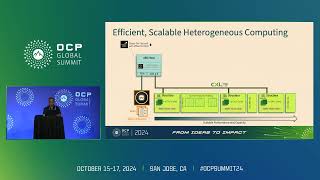
Memory Wall Mitigation and Acceleration of AI Workloads Using CXL Near Memory Computing
Explore CXL-based Near Memory Compute architectures for hyperscale environments, focusing on acceleration solutions for data-intensive workloads and memory optimization techniques.
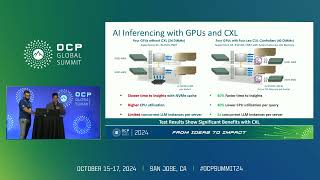
Optimizing AI Inferencing with CXL Memory - Memory Tiering Strategies for Enhanced Performance
Explore how CXL-attached memory revolutionizes AI inference systems, enhancing performance and scalability for Large Language Models while optimizing memory bandwidth and reducing latency.
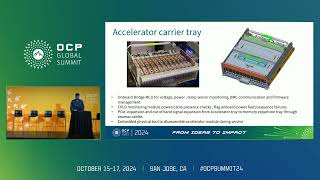
Supporting Meta ML Accelerators on the Grand Teton Platform
Discover how Meta modifies the Grand Teton platform to integrate ML accelerators, exploring hardware design changes, carrier card implementation, and rack configuration for enhanced performance.
Near Memory Compute for AI Inferencing - Optimizing Data Center Design and TCO
Explore innovative approaches to AI inferencing optimization through Near-Memory Compute technology, focusing on reduced latency, cost efficiency, and sustainable data center design solutions.
CXL Memory Disaggregation - Use Cases and System Benefits in Multi-host Environments
Explore advanced memory pooling and sharing in CXL 3.1, focusing on datacenter cost reduction, dynamic resource allocation, and performance optimization for distributed computing frameworks.
Emerging Memory Architecture Challenges with CXL Introduction
Explore CXL memory's impact on server systems through performance analysis of Meta's CacheLib and Hazelcast, examining bandwidth expansion and optimization strategies for next-gen memory architectures.
Breaking Through the Memory Wall with CXL - Accelerating Computing Performance
Discover how CXL-attached memory solutions overcome processor-memory bottlenecks, enabling enhanced performance for AI applications and in-memory databases in modern data centers.
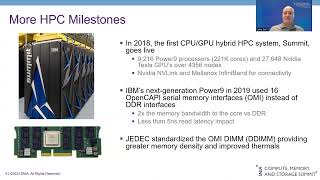
Proprietary Interconnects and CXL: Evolution and Future Coexistence
Explore the evolution of open interconnects and CXL technology, examining their role alongside proprietary connectivity in modern compute architectures and future computing solutions.
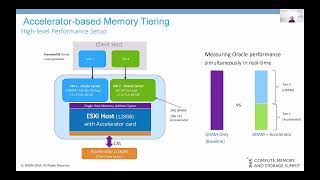
CXL Accelerator-Based Memory Solutions - Bringing Unique Customer Value
Explore how VMware and Samsung leverage CXL Type-2 accelerator solutions to enhance memory capabilities, reduce costs, and improve workload performance through innovative hardware-software integration.
CXL Type 2 Device Passthrough with VFIO - Enhancing Data Center Performance
Explore CXL Type 2 device passthrough using VFIO, covering architecture, requirements, and kernel changes for enhanced data center performance and efficiency.
Managing Memory Tiers with CXL in Virtualized Environments
Explores hardware-managed memory tiering with CXL, introducing Intel® Flat Memory Mode and Memstrata allocator to optimize performance and reduce contention in virtualized cloud environments.
HydraRPC - Efficient RPC System Using CXL-Attached HDM
Explores HydraRPC, utilizing CXL-attached HDM for efficient data transmission, eliminating network rounds and memory copying. Evaluates performance on real CXL hardware, showcasing potential for building efficient RPC systems.