Beyond Observability - Aligning Technology Performance to Business Outcomes
Explore the integration of business intelligence and observability to create a comprehensive feedback loop, aligning technology performance with business outcomes and customer satisfaction in real-time.
Giving Away Your Secrets - Opening Metrics Up to Users
Explore methods for providing users direct visibility into platform metrics, enhancing problem-solving capabilities and reducing support load. Learn approaches for different scenarios and common challenges.
An SRE Guide to Linux Kernel Upgrades
Demystifying Linux kernel releases and providing strategies for regular, low-risk upgrades to enhance system security and stability while dispelling common misconceptions about kernel updates.
Humane On-call
Explore strategies for implementing and improving on-call practices in SRE and tech roles, emphasizing its importance and offering actionable ideas for more humane and effective 24/7 operations.
Towards Zero Carbon - Implementing Sustainable Battery Lifecycle Management in Data Centers
Innovative solution for sustainable battery lifecycle management in data centers using IoT, AI, and real-time monitoring to reduce costs, prevent downtime, and achieve zero-carbon waste diversion goals.
Finding the Needle in the Haystack - Predicting Storage Device Failures in Data Centers
Practical approach to predicting storage device failures in data centers using multi-phase proactive sampling, addressing challenges of accuracy, performance, and cost-effectiveness for Site Reliability Engineers.
The Only Constant Is Change - Lessons from a 25 Year SRE Career
Explore the evolution of SRE over 25 years, gaining insights on essential career skills and future trends in tech infrastructure management from an industry veteran's perspective.
Hold My Beer - Load Testing in Production on Autopilot
Discover how automated load testing in production enhances system reliability, developer confidence, and business performance while minimizing risks and human intervention.
Real World Debugging with eBPF
Explore eBPF for debugging production issues in Golang, overcoming traditional tool limitations. Learn practical techniques and gain insights for immediate problem-solving without special debug modes.
Transformation Journey of E2E Customer Flow Testing to Proactive Synthetic Monitoring System
Evolving PayPal's E2E customer flow testing into a proactive synthetic monitoring system for improved incident prevention, faster detection, and enhanced site reliability.
Lessons Learned Running GKE Clusters on Spot Instances
Explore cost-saving strategies and challenges of running GKE clusters on Spot Instances, including capacity management, edge cases, and the importance of SRE principles in this dynamic environment.
LiveMLP - ML Platform for Assisting Contact Center Agents in Real-Time
Explore a real-time ML platform designed to assist contact center agents, addressing challenges in throughput, latency, and fault tolerance while improving customer support efficiency.
Are We All on the Same Page? Let's Fix That
Explore Adaptive Paging, an innovative alert handler leveraging tracing and semantic conventions to identify and page teams closest to issues in complex distributed systems, reducing alert fatigue.
How Safe Is Your Domain?
Deep-dive into domain and DNS safety, exploring threat vectors, detection methods, and mitigation strategies for improved security and availability of infrastructure domains and subdomains.
Cultivating Accountability and Resilience
Explore DBS Bank's framework for building resilient infrastructure through cultural transformation, focusing on collaborative approaches and system-wide improvements for a proactive tech environment.
Leveraging Analytics for Technical Efficiency and Enhanced User Experience
Explore innovative analytics-driven services for improved site reliability, including automated outage management, predictive Slackbot solutions, and user engagement optimization through event data analysis.
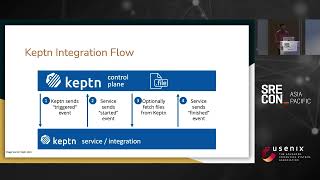
Performance Testing in Keptn Using K6
Explore Keptn's integration with K6 for scalable performance testing in delivery pipelines, including SLO evaluation and quality gates for efficient service monitoring and optimization.
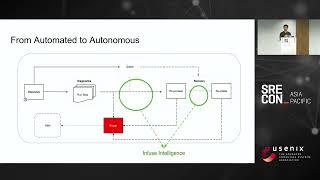
Autonomous Automation - How Cloudflare Handles Server Diagnostics and Recovery at Scale
Explore Cloudflare's autonomous system for server diagnostics and recovery at scale. Learn to transform automation into autonomy, applying SRE principles for increased efficiency and productivity.
Practical Magic - The Resilience Potion & Security Chaos Engineering
Explore the five-ingredient Resilience Potion Recipe to foster systems resilience and guide security chaos engineering transformation, with practical opportunities for each ingredient in software development.
Dumping NTHashes from Azure AD
Explore techniques for extracting NTHashes from Azure AD, uncovering potential security vulnerabilities in cloud identity management systems.
The Power of Coercion Techniques in Windows Environments
Explore coercion techniques in Windows environments, their impact on IT security, and strategies for defense against these powerful attack vectors.