Exploring Foundation Models - Session 3
Dive into the world of foundation models with experts Anthony Cohn and Yarin Gal, exploring cutting-edge developments and implications in artificial intelligence.
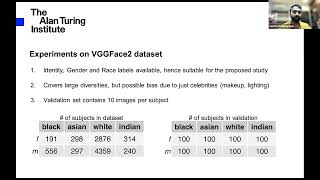
Fairness in Commercial Face Recognition Algorithms - Session 3
Explore fairness issues in commercial facial recognition systems, examining biases and ethical implications for diverse populations.
End-to-End AI Developer Journey with Containerized Assets Using Intel DevCatalog and DevCloud
Explore containerized AI development using Intel DevCatalog and DevCloud. Learn to access, customize, and deploy AI assets on various Intel hardware, leveraging OpenVINO for training and inference.
Creating Production-Ready Containers - Securing and Optimizing for Node.js
Learn to secure and optimize Node.js containers for production, focusing on image size, build speed, and security. Explore techniques like multistage builds and open-source tools for efficient, confident deployment.
Optimizing .NET Docker Images for Production and Development
Optimize .NET Docker images for production: build time, layers, pitfalls. Enhance development with remote debugging, hot-reloading. Learn techniques for efficient containerized .NET applications.
Creating Secure Node.js Docker Images - Best Practices and Optimization
Learn to build optimized and secure Node.js Docker images with production-grade guidelines, addressing pitfalls and insecurities in Dockerfile directives for Docker-based applications.
Creating Secure Node.js Docker Images - Best Practices and Optimization
Learn to build optimized and secure Node.js Docker images with production-grade guidelines, addressing pitfalls and insecurities in Dockerfile directives for Docker-based applications.

Do Not Ignore .dockerignore - Optimizing Docker Builds
Optimize Docker builds and enhance security by leveraging .dockerignore files effectively. Learn best practices and implementation strategies.
How to Build an Item Detection App with No-Code AI Vision at the Edge
Build a retail item detection system using Node-RED and Docker. Learn setup, containerization, and deployment for efficient edge AI vision applications without coding.
Beyond Automation: Using AI for Good
Exploring AI's potential for societal advancement, ethical considerations, and future implications beyond automation, featuring insights from industry experts and policymakers.
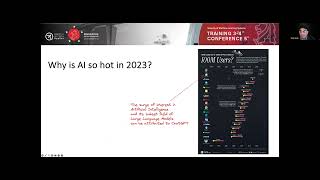
Security of Machine Learning Systems
Explore security challenges in AI and ML systems, including adversarial attacks and MLOps. Learn to apply pen testing skills to ML, with demonstrations on manipulating image recognition and NLP models.
Navigating Vision Systems with Weights & Biases and SmartCow
Explore computer vision advancements with Weights & Biases and SmartCow. Learn about Ultralytics, object detection metrics, and practical implementations for enhancing ML projects.
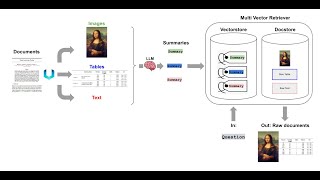
Using LangChain with Multimodal AI to Analyze Images in Financial Reports
Learn to analyze financial reports with images using GPT-4 Vision and LangChain. Explore multimodal RAG techniques, codebase implementation, and result evaluation for enhanced document analysis.
Explainable AI in Healthcare: Oxford-Style Debate - November 2023
Engaging Oxford-style debate on the necessity of explainable AI in healthcare, featuring expert speakers discussing its role in shaping the future of medical technology.

Node.js Best Practices in Docker - 2023 Edition
Explore the latest Node.js strategies for Docker, including Wolfi images, Docker Scout analysis, Compose Sync, and docker init. Learn about Dockerfile advancements, process management, and GitHub Actions for efficient development.
Computer Vision and Language Models: Bridging the Modality Gap
Explore how large language models are transforming computer vision through projects like VisProg and VoxelGPT, with insights on challenges, prompt engineering, and future prospects.
Autogen and Local LLMs Create Realistic Stable Diffusion Model Autonomously
Explore AI-powered creation of realistic SDXL models using autonomous agents and local LLMs. Learn setup, implementation, and troubleshooting for cutting-edge AI image generation techniques.
ML On-Device: Building Efficient Models
Explore on-device machine learning for efficient, privacy-preserving models on mobile and edge devices. Learn about real-time AI applications, model optimization, and deployment strategies.
Physics-informed Machine Learning for Robust Pedestrian Detection in Embedded Low-power Systems
Innovative machine learning algorithm for efficient pedestrian detection in urban areas using neuromorphic sensors, combining physical motion models for accurate real-time tracking day and night.
Practical Approach for Fingerprint Recognition by Merging LBP and PCA
Explore fingerprint recognition using LBP and PCA techniques for improved accuracy. Dr. Solanki demonstrates practical implementation, enhancing computer science applications in forensic analysis.
LLaVA: The New Open Access Multimodal AI Model
Explore LLaVA, a cutting-edge open-access multimodal AI model. Learn about its capabilities, live demo, GitHub repository, research papers, and available models on Hugging Face.