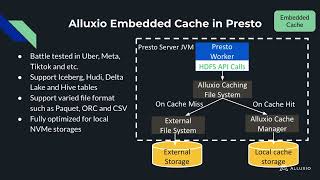
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
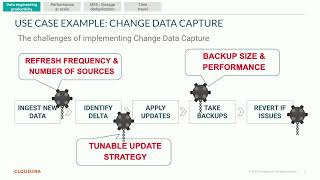
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.
New Features of Apache NiFi - Tips and Techniques
Explore Apache NiFi's latest features, processors, and best practices. Build efficient data flows using cutting-edge techniques, with tips and guides for optimal implementation.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
The Free Lunch is Over: Dealing with Unstructured Data in the Era of LLMs
Explore unstructured data processing using ML, LLMs, and Apache tools. Learn to handle audio, images, and text with vector embeddings for natural language analysis in data engineering pipelines.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.
Optimizing HDFS Performance: Balanced Utilization of Hardware Accelerators and ARM64 Multi-Implementation - Transparent Encryption
Optimize HDFS Transparent Encryption performance by balancing CPU cores and hardware accelerators. Learn to leverage OpenSSL 3.0 for dynamic resource allocation and improved efficiency in cloud services.
Design and Practice of OPPO Big Data Spark and Flink Engine Diagnosis System
Explore OPPO's engine diagnosis platform for optimizing Spark and Flink performance in big data operations, enhancing problem-solving efficiency and resource utilization.
Meta Velox - Advanced Database Systems - Lecture 23
Explore Meta's Velox query execution engine, its architecture, and its role in modern data processing systems. Learn about its features and performance optimizations.

Snowflake Data Warehouse Internals - Lecture 21
Explore Snowflake's data warehouse architecture, design principles, and internal mechanisms for efficient cloud-based data management and analytics.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 20
Explore Databricks Photon and Spark SQL's advanced features for efficient data processing and analysis in modern database systems.
Modern Analytical Database Systems - Lecture 2
Explore modern analytical database systems, covering distributed architectures, query execution, and OLAP commoditization in this advanced CMU lecture.
Snowflake Database Architecture Overview - Lecture 25
Explore Snowflake's cloud-based database architecture, including query execution, optimization, and workload management, with insights from industry experts.
Domain Knowledge Augmented AI for Databases - Alibaba
Explore domain knowledge augmented AI for databases, focusing on Alibaba's innovative approaches and their impact on database management systems.
Logging Modernization and Cybersecurity at Scale with MiNiFi, Kafka and Flink
Modernize logging and enhance cybersecurity using MiNiFi, Kafka, and Flink. Learn efficient log collection, processing, and streaming analytics for global network monitoring and alert generation.
Git for Data Lakes: How LakeFS Scales Data Versioning to Billions of Objects
Learn how lakeFS enables Git-like versioning for data lakes, solving challenges of object storage and scaling to billions of objects without compromising performance. Explore branching, committing, and merging for petabyte-scale data management.
Accelerating Apache Spark Workloads with Apache DataFusion Comet
Explore Apache DataFusion Comet's potential to enhance Apache Spark performance, optimizing data processing workflows and improving efficiency in large-scale analytics.
Apache Arrow DataFusion - A Fast, Embeddable, Modular Analytic Query Engine
Explore Apache Arrow DataFusion's fast, embeddable, and modular analytic query engine capabilities with insights from expert Andrew Lamb.
Yellowbrick Data Warehouse System - Lecture 21
Explore Yellowbrick's innovative data warehouse system, its architecture, and performance optimizations for analytical workloads in this advanced database systems lecture.