Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
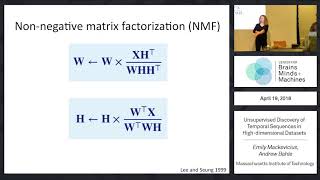
Unsupervised Discovery of Temporal Sequences in High-Dimensional Datasets
Explore unsupervised discovery of temporal sequences in high-dimensional datasets using seqNMF, a tool extending convolutional NMF. Learn to extract and validate neural sequences from large-scale recordings.
What is Your Data Worth? Equitable Data Valuation in Machine Learning
Explore equitable data valuation in machine learning, focusing on Data Shapley Value and its applications in healthcare, face recognition, and NLP.
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
Enable Production ML with Databricks Feature Store
Simplify production ML with Databricks Feature Store. Learn to overcome data challenges, enable real-time inference, and streamline ML projects using a unified data lakehouse platform integrated with Apache Spark and MLflow.

Delta Live Tables: Modern Software Engineering for ETL Pipelines
Learn how Delta Live Tables simplifies ETL, enhances data pipeline reliability, and automates tasks. Discover modern software engineering practices for efficient data transformation and improved analytics, data science, and ML outcomes.
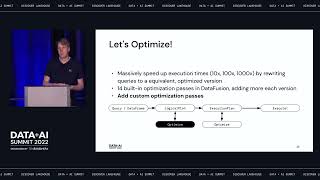
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
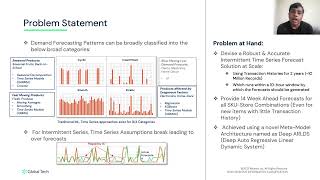
Intermittent Demand Forecasting at Scale Using Meta-Modeling - Deep Auto-Regressive Linear Dynamic Systems
Discover Walmart's innovative solution for predicting demand of slow-moving items using meta-modeling, combining linear dynamic systems and deep auto-regressive networks for accurate forecasts across thousands of SKUs and stores.
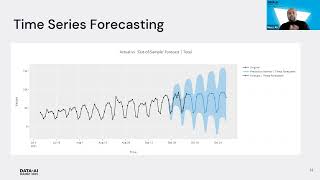
Time Series Forecasting with PyCaret
Explore automated time series forecasting with PyCaret's low-code module. Learn setup, EDA, training, and forecasting techniques to streamline your predictive modeling workflow.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
Solving Business Problems with Data - Delivering Value Through Use Case Deconstruction
Explore strategies for aligning data teams with business goals, focusing on use case deconstruction and value delivery. Learn to bridge the gap between technical expertise and practical business impact.
Data Culture Outside Silicon Valley - Building Teams and Blocking Spam Calls
Exploring data culture beyond Silicon Valley, featuring First Orion's innovative approach to spam call blocking and insights on building effective data teams in Arkansas.
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.

Understanding Spark SQL - Lesson 6
Explore Spark SQL's powerful features for data engineering, including query optimizations and support for Python, R, and Scala, enhancing parallel processing performance.
Using the Data Science Process - Lesson 5
Explore the data science process from project inception to completion, covering key steps for successful implementation in Databricks and Apache Spark projects.
Create a Spark Cluster - Master Databricks and Apache Spark Step by Step - Lesson 4
Learn to create and use Apache Spark clusters, understand their differences from Databricks, and explore data querying with Zeppelin notebooks in this step-by-step guide.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
Understand Slowly Changing Dimensions
Learn to handle Slowly Changing Dimensions in data warehousing, including SCD types, their implementation, and impact on star schema design. Gain expertise for interviews and practical applications.