Distributed Transaction Processing Databases - Lecture 22
Explore distributed transaction processing in databases, covering key concepts, challenges, and solutions for maintaining consistency across multiple nodes.
Chroma Vector Database: Retrieval for LLMs
Explore Chroma Vector Database's role in enhancing LLM retrieval capabilities with insights from industry experts Hammad Bashir and Liquan Pei.
Distributed Data Warehouse OLAP Databases - Lecture 23
Explore distributed data warehouse OLAP databases, covering architecture, query processing, and optimization techniques for large-scale analytical systems.
Redis, CockroachDB, Snowflake, MangoDB, and TabDB - Potpourri of Database Systems - Lecture 25
Explore Redis, CockroachDB, Snowflake, MangoDB, and TabDB in this comprehensive overview of modern database systems, covering their architectures, features, and use cases.
Data Formats and Encoding for Advanced Database Systems - Part 1
Explore advanced database concepts, focusing on data formats and encoding techniques for efficient storage and retrieval in modern systems.
Vectorized Query Execution Using SIMD - Lecture 6
Explore vectorized query execution using SIMD in advanced database systems, focusing on performance optimization techniques and modern hardware utilization.

User-Defined Function Optimizations in Advanced Database Systems - Lecture 11
Explore advanced optimization techniques for user-defined functions in database systems, enhancing query performance and system efficiency.

Realtime Data Streaming - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using Apache Airflow, Kafka, Spark, and Cassandra. Learn end-to-end data engineering, from ingestion to processing and storage, all containerized with Docker.
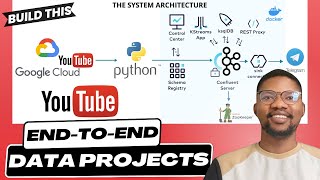
Google Cloud Real-Time Streaming - End-to-End Data Engineering Project
Build an end-to-end data engineering pipeline for real-time YouTube Analytics, using Python, Google Cloud, Docker, and Kafka. Learn to fetch, process, and stream data, with instant Telegram notifications.
Football Data Analytics: Azure End-to-End Data Engineering Project
Extract, clean, and analyze football data using Apache Airflow, Azure services, and Tableau. Build a comprehensive data pipeline from Wikipedia to interactive visualizations.
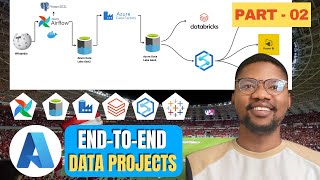
Football Data Analytics: Azure End-to-End Data Engineering Project - Part 2
Extract, store, and analyze football data using Azure services and Apache Airflow. Develop end-to-end data engineering skills through hands-on implementation of a real-world project.
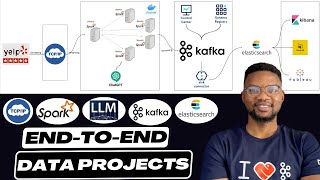
Realtime Socket Streaming with Apache Spark - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using TCP/IP Socket, Apache Spark, OpenAI LLM, Kafka, and Elasticsearch. Process 7 million records for sentiment analysis and efficient data indexing.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.
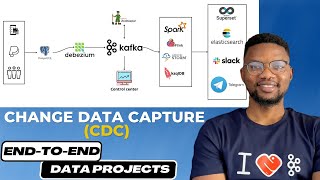
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Developing gRPC Communication with Quarkus and Microprofile
Explore gRPC for efficient API development in microservices, leveraging Quarkus and Microprofile. Learn fundamentals, best practices, monitoring, error handling, and advanced features.
Developing gRPC Communication with Quarkus and Microprofile
Explore gRPC for efficient API development in microservices, leveraging Quarkus and Microprofile. Learn best practices, performance optimization, monitoring, error handling, and advanced features.
Beyond REST and CRUD: Integration Patterns in Microservices
Explore advanced integration patterns for microservices beyond REST and CRUD, enhancing system design and communication in distributed architectures.
Fraud Detection Use Case with Red Hat OpenShift Data Science
Explore hands-on fraud detection techniques using a practical GitHub repository, guided by experienced software engineers.
Server-Side WebAssembly - Understanding Its Potential in Cloud Computing
Explore server-side WebAssembly's potential in cloud computing. Learn its basics, advantages over containers, and practical applications through a demonstration of current capabilities.
Server-Side WebAssembly - Understanding Its Potential in Cloud Computing
Explore WebAssembly's potential in cloud computing, its comparison to containers, and how to start with server-side WebAssembly. Includes a demonstration of capabilities and future possibilities.
Debezium - Building Streaming Data Pipelines with Change Data Capture
Explore Debezium's features for building streaming data pipelines using popular databases as sources, with a focus on Apache Kafka integration and alternative data sinks.