Conversation Simulator: A Real Life Case Leveraging OpenAI's API for Crisis Text Line
Explore a conversation simulator leveraging OpenAI's API for crisis response training, reducing anxiety for new responders and enhancing support for people in crisis.
Data Warehouses are Gilded Cages - What Comes Next
Explore DuckDB's potential to revolutionize data analytics, shifting from centralized warehouses to powerful local processing. Learn how this approach can enhance efficiency and user control in data management.
CDC Stream Processing with Apache Flink
Explore Apache Flink's capabilities as a data integration hub, focusing on its SQL engine for changelog processing, CDC data handling, and materialized view maintenance. Learn about data source semantics and system integrations.
How to Build a Streaming Database in Three Challenging Steps
Explore the foundational choices and trade-offs in building a streaming database with Frank McSherry, Chief Scientist at Materialize. Learn manageable approaches to this complex task.
Change Data Streaming Patterns with Debezium and Apache Flink
Explore change data capture with Debezium and Apache Flink for microservices. Learn outbox pattern, strangler fig pattern, and saga orchestration for reliable data exchange and long-running transactions.
Ten Years of Building Open Source Standards: From Parquet to Arrow to OpenLineage
Explore the journey of building open-source data standards, from Apache Parquet to Arrow to OpenLineage. Gain insights into successful project ideation, growth, and ecosystem impact in data management.
How Investors Think About Data - Trends in Data, ML, and AI Investing
Explore investor perspectives on data, AI, and ML from top venture firms. Gain insights into investment trends, criteria for early-stage teams, and future opportunities in the data infrastructure landscape.
Designing for Intelligence: Patterns and Practices for AI-Powered Products
Explore patterns and practices for designing AI-powered products, drawing insights from GitHub Next's experiences in developing tools like GitHub Copilot for the software development lifecycle.
How Riot Games Uses Data to Maximize Engagement and Enjoyment
Explore data challenges in League of Legends, including model deployment, ML stack evolution, player-facing ML, and decision science at scale for improved gaming experiences.
Creating Our Own Kubernetes and Docker to Run Data Infrastructure
Explore Modal's custom container infrastructure, including a Rust-based file system and runtime, to understand how they launch 1000s of large containers rapidly for efficient data processing.
Generative AI for Search
Explore the powerful role of generative AI in search, focusing on NLP and Vision. Discover key challenges and promising directions through anecdotes and organizing principles.
Generative AI for Product Builders
Explore generative AI's potential to enhance products, accelerate workflows, and unlock creativity. Learn about technical challenges and solutions in building AI-powered products.
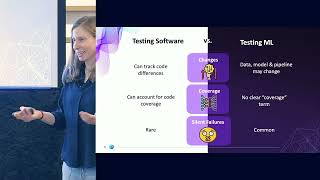
Testing Models and Data in CI/CD Pipelines for Machine Learning
Explore best practices for testing ML models in CI/CD pipelines. Learn to validate models and data using deepchecks, addressing common pitfalls and ensuring continuous relevance and trustworthiness.
Everything I Know About Data Science I Learned from Model Railroading
Explore parallels between data science and model railroading, uncovering valuable insights for building real-world models and improving data science practices.
Real-time Schema Discovery in Distributed Systems
Explore real-time schema discovery in high-volume distributed systems. Learn about schema versioning, conflict detection, compatibility, and normalization without batching processes.

Declarative Orchestration: Why You've Been Thinking About the Wrong DAG the Entire Time
Explore declarative, asset-oriented orchestration in data pipelines. Learn how this approach simplifies tasks, ensures data integrity, and implements Data Mesh as a living asset graph.

What Makes for an Effective Data Practitioner in 2024
Gain insights on essential skills and career development for data practitioners in 2024. Learn from an industry expert about navigating complexities and advancing in the field.
Building Responsible and Trustworthy Generative AI Products at LinkedIn
Explore LinkedIn's ethical AI development, focusing on responsible Generative AI practices. Gain insights into foundational principles and architecture guiding their AI journey and cutting-edge products.
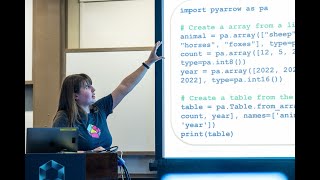
Time Series Analytics with Apache Arrow, Pandas, and Parquet - A 101 Introduction
Explore efficient time-series data handling using Apache Arrow and Parquet. Master open-source technologies for high-performance analytics applications.
Building a Unified Feature Platform with DuckDB and Arrow
Explore ML feature platform development using DuckDB and Arrow. Learn scaling strategies, DuckDB extension implementation, DeltaLake interoperability, and performance comparison with Spark.
The Future of Data Engineering in a Post-AI World
Explore AI's impact on data engineering, including ETL automation, data warehouses, and emerging technologies. Learn to leverage AI for significant business impact in the evolving data landscape.