Why Are Distributed Systems So Hard?
Explore the challenges of distributed systems, including CAP theorem myths, network partitions, consensus algorithms, and human factors, with cat-illustrated examples.
Tracing, Fast and Slow - Digging into and Improving Your Web Service's Performance
Explore techniques for tracing and improving web service performance, including black & white box tracing, distributed systems tracing, and various tools to measure and enhance service efficiency.
Lightning Talks
Lightning talks on diverse SRE topics: incident response, distributed systems, resource management, automation, operational maturity, and monitoring. Insights from industry experts on improving reliability and efficiency.
Fault Tree Analysis Applied to Apache Kafka
Explore fault tree analysis techniques to enhance Apache Kafka cluster resilience, drawing insights from Lyft's experience in bulletproofing their deployments.
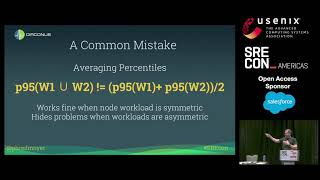
Latency SLOs Done Right
Explore correct approaches to calculating latency SLOs using histograms and mathematically accurate quantiles, improving service level objectives for more effective monitoring and performance management.
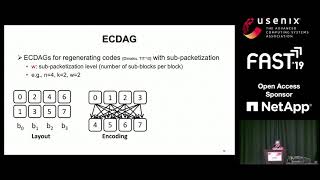
OpenEC - Toward Unified and Configurable Erasure Coding Management in Distributed Storage Systems
Unified framework for deploying erasure coding solutions in distributed storage systems, simplifying integration and optimizing repair performance.
Orion - A Distributed File System for Non-Volatile Main Memory and RDMA-Capable Networks
Explores a novel distributed file system design optimized for non-volatile main memory and RDMA networks, achieving high performance for metadata and data access while maintaining byte addressability.
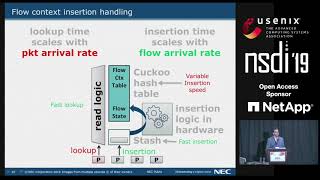
FlowBlaze - Stateful Packet Processing in Hardware
Innovative hardware-based solution for stateful packet processing, enabling high-speed network functions with low latency and power consumption using Extended Finite State Machines on programmable NICs.
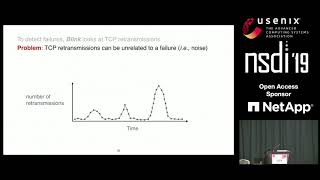
Blink - Fast Connectivity Recovery Entirely in the Data Plane
Explores programmable switches for rapid rerouting using TCP-induced signals to detect failures. Presents Blink, a data-driven system analyzing TCP flows at line rate to quickly recover connectivity in the data plane.
Size-Aware Sharding for Improving Tail Latencies in In-Memory Key-Value Stores
Innovative size-aware sharding technique for in-memory key-value stores, reducing tail latencies and improving throughput by avoiding head-of-line blocking and optimizing request distribution across cores.
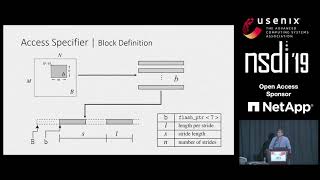
BLAS-on-Flash - An Efficient Alternative for Large Scale ML Training and Inference
Efficient alternative for large-scale ML tasks using SSD-resident matrices, enabling near in-memory performance on a single workstation. Outperforms distributed systems for complex algorithms like eigensolvers.
Effectively Prefetching Remote Memory with Leap
Innovative prefetching solution for remote memory access, improving latency and performance in memory disaggregation systems through online algorithms and efficient kernel data paths.
I'm Putting Sloths on the Map
Explore Sloth, a Go tool for simulating network failures in cloud infrastructure. Learn how it helps discover and fix issues in monitoring, graceful degradation, and usability through controlled network disruptions.
A Practical Guide to Monitoring and Alerting with Time Series at Scale
Explore time series-based alerting methods and practical examples in Prometheus to reduce alert spam and improve production hygiene for more efficient monitoring at scale.
I Can't Believe It's Not Causal! Scalable Causal Consistency with No Slowdown Cascades
Explore Occult, a scalable geo-replicated data store providing causal consistency without slowdown cascades. Learn about its design, implementation, and evaluation using PC-PSI for efficient transaction handling.
vCorfu - A Cloud-Scale Object Store on a Shared Log
Explore vCorfu, a cloud-scale object store built on a shared log, offering strong consistency, efficient transactions, and global snapshots while outperforming traditional NoSQL databases.
Encoding, Fast and Slow - Low-Latency Video Processing Using Thousands of Tiny Threads
Innovative video processing system using cloud functions and parallel computing for low-latency editing and encoding of high-resolution videos, including 4K and VR content.
Burnout and Ops
Strategies for preventing and recovering from burnout in infrastructure engineering, with insights on setting boundaries, improving work conditions, and maintaining long-term career sustainability.
Reliability When Everything Is a Platform - Why You Need to SRE Your Customers
Explore the concept of SREs taking joint operational responsibility for customer-built systems on platforms, addressing challenges and discussing future implications for SRE as a discipline.
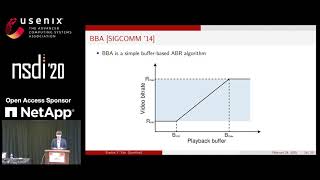
Learning in Situ - A Randomized Experiment in Video Streaming
Randomized trial of video-streaming algorithms reveals challenges for sophisticated schemes in real-world settings. New algorithm developed using in situ learning outperforms others.
Gryff - Unifying Consensus and Shared Registers
Unifying consensus and shared registers for geo-replicated storage with linearizability and low tail latency. Introduces carstamps for efficient ordering of reads and writes in distributed systems.