Productionizing Machine Learning Pipelines with Databricks and Azure ML
Jumpstart ML projects with Databricks and Azure ML. Learn to build, track, and deploy production-ready pipelines using tools like MLflow, TensorFlow, and PyTorch for efficient, reproducible data science workflows.
Azure and Databricks Enabling Personalized Customer Experience at CVS Health
Explore how CVS Health leveraged Azure and Databricks to personalize customer experiences, implement machine learning models, and drive business value through data-driven decision-making and experimentation.
Deep Learning for Price Action Prediction Using Databricks and AWS
Explore deep learning techniques to enhance price action prediction using Databricks and AWS. Learn to optimize technical indicators and train models with Amazon SageMaker for improved financial forecasting.
The Killer Feature Store - Orchestrating Spark ML Pipelines and MLflow for Production
Explore feature store implementation as an orchestration engine for ML pipeline stages using Spark and MLflow, focusing on deployment management, A/B testing, discovery, and governance.
Benchmarks and How-Tos for Convolutional Neural Networks on HorovodRunner-Enabled Apache Spark Clusters
Explore benchmarks and implementation techniques for distributed deep learning using HorovodRunner on Apache Spark clusters, focusing on CNN tasks and scaling efficiency for both GPU and CPU clusters.
Tuning Machine Learning Models - Scaling, Workflows, and Architecture
Automating and scaling ML model tuning using Hyperopt and Apache Spark. Best practices for workflows, architecture, and optimization in hyperparameter tuning for improved performance and accuracy.
Productionalizing Models through CI/CD Design with MLflow
Explore MLflow integration with CI/CD for streamlined model deployment. Learn to design and implement automated pipelines using the model registry, enhancing efficiency in machine learning workflows.
Apache Spark NLP for Healthcare - Building Real-World AI Systems
Explore real-world healthcare AI systems using NLP, covering patient risk prediction, diagnosis automation, and revenue optimization. Learn key considerations for building domain-specific models and scalable ML pipelines.
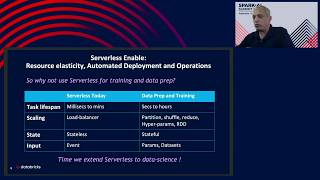
Productionizing Machine Learning with Microservices Architecture
Learn to deploy ML models as microservices using Spark, enabling auto-scaling, versioning, and security. Discover how to aggregate real-time and historical data for inferencing and create actionable insights.
Apache Pulsar - Next Generation Messaging and Queuing System
Overview of Apache Pulsar's architecture, features, and benefits as a scalable messaging system with unified storage, processing, and serverless capabilities for building end-to-end streaming applications.
Scaling Up AI Research to Production with PyTorch and MLFlow
Explore PyTorch's latest advancements in AI research and production, including distributed training, model optimization, and deployment using MLFlow, with insights on scaling and efficiency.
Model Explanation and Prediction Exploration Using Spark ML
Explore techniques for explaining non-linear models, showing feature contributions, and performing what-if analysis using Spark ML. Implement these methods to enhance model interpretability and enable interactive prediction exploration.
Delivery of Deep Transformer NLP Models Using MLflow and AWS SageMaker for Enterprise AI
Learn to deploy deep transformer NLP models using MLflow and AWS SageMaker for enterprise AI, covering the full machine learning lifecycle and CI/CD pipelines for production-quality implementation.
Building a Pipeline for State-of-the-Art NLP Using Hugging Face Tools
Learn to build state-of-the-art NLP pipelines using Hugging Face tools. Explore tokenization, transformer networks, and various NLP tasks like sentiment analysis and question answering.
Automated and Explainable Deep Learning for Clinical Language Understanding
Explore advanced deep learning techniques for clinical NLP, including automated model training, explainable AI, and scalable architectures to extract critical healthcare insights from unstructured medical notes.
Improving Broadcast Joins in Apache Spark SQL
Discover techniques to enhance broadcast joins in Apache Spark SQL, including executor-side broadcasting and memory optimization, for improved performance in large-scale ETL pipelines and complex data processing tasks.
Productionizing Deep Reinforcement Learning with Spark and MLflow
Aprenda a aplicar Deep Reinforcement Learning em escala usando Spark e MLflow para personalização de jogos e aumento de engajamento, com dicas práticas para superar desafios de produção.
Zeus - Uber's Highly Scalable Distributed Shuffle as a Service
Explore Uber's Zeus: a highly scalable, distributed shuffle service powering data processing. Learn its architecture, integration with Spark, and performance advantages over traditional external shuffle methods.
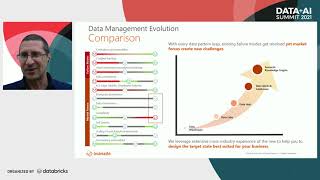
The Shift to Data Mesh: Fundamentals and Implementation Strategies
Explore Data Mesh fundamentals and how Avanade helps clients adopt a distributed, domain-led approach to improve data modeling, governance, and incremental transformation for faster performance.
Efficient Distributed Hyperparameter Tuning with Apache Spark
Learn to efficiently distribute hyperparameter tuning workloads using Apache Spark, avoiding common pitfalls and optimizing performance. Explore best practices with Hyperopt and joblib-spark for scaling ML model training.
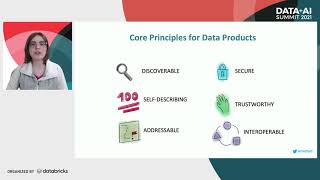
Architect's Open-Source Guide for Data Mesh Architecture
Explore Data Mesh architecture, its principles, benefits, and implementation challenges. Learn about open-source tools like Apache Spark for building effective Data Mesh systems in real-world scenarios.