Clustering: Clusterability, Voronoi Diagrams, and Assignment-based Clustering - Lecture 22
Explore clustering fundamentals through Voronoi diagrams and assignment-based techniques while learning to assess data clusterability and implement effective grouping strategies.
(Almost) All of Entity Resolution
Explore entity resolution's applications, history, and current research in data integration, from foundational work to modern approaches in various fields like human rights and medicine.
Distance Metric Learning and Mutual Funds Categorization - Part 1
Explore distance metric learning for mutual fund categorization, resolving paradoxes in previous research and improving accuracy in identifying similar funds for various applications.
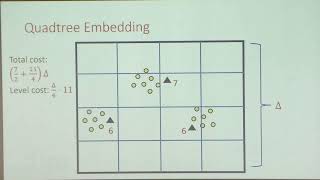
Fast Streaming Euclidean Clustering with Constant Space
Explore streaming algorithms for k-median and k-means clustering, achieving constant space complexity independent of data size and aspect ratio. Improve space and update time for approximate subspace embeddings.
MongoDB - Stepping Around the Pitfalls
Explore MongoDB's pitfalls, marketing claims, and practical solutions for data integrity, clustering, transactions, and performance optimization.
Frameworks Unplugged: Building Distributed Systems in Pure Java
Dive deep into building distributed systems using pure Java, exploring underlying principles and algorithms beyond framework abstractions. Gain insights into REST, HTTP methods, and cluster state management.
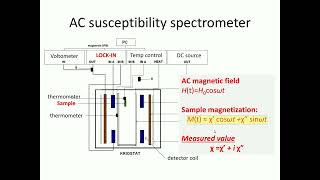
Application of Unsupervised Learning to AC Susceptibility Measurements of High-Temperature Superconductors
Explore unsupervised learning applications in analyzing AC susceptibility measurements of high-temperature superconductors, focusing on clustering techniques and data representation methods.
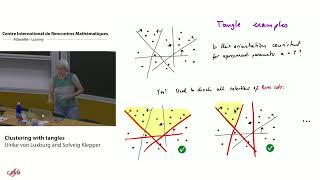
Clustering with Tangles - Machine Learning and Signal Processing on Graphs
Explore clustering with tangles, covering partitions, agreement parameters, cost functions, and applications in machine learning and signal processing on graphs.
Document Summarization: Langchain Summarization Chains, Clustering and LLMs
Explore document summarization using Langchain, Hugging Face Transformers, and clustering techniques for efficient text analysis and insights.
A Nearly Tight Analysis of Greedy k-means++
Explore the greedy k-means++ algorithm's performance, analyzing its approximation guarantees and comparing it to the original k-means++ method for solving the k-means problem.
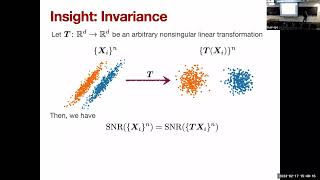
Clustering a Mixture of Gaussians with Unknown Covariance - Lecture
Explore clustering with Gaussian mixtures, focusing on maximum likelihood estimation, Max-Cut solutions, and efficient algorithms. Investigate statistical-computational gaps and challenges in high-dimensional settings.
Data Preparation Tips and Tricks for Machine Learning
Master data preparation techniques for AI models, including filtering, balancing, and synthetic dataset creation. Explore clustering methods, chat templates, and handling mixed-language data for improved model performance.
Feature Selection and Clustering with a Quantum Annealer - QuantumCLEF 2024
Dive into quantum annealing techniques for feature selection and clustering through hands-on demonstrations and practical implementations for advanced data analysis tasks.
Visualization for Data Science - Filtering, Aggregation, and Clustering
Master data visualization techniques through filtering, aggregation, and interactive queries, exploring real-world applications like gerrymandering analysis and clustering methods including K-means and DBScan.
Introduction to Machine Learning - Clustering - Part 3
Explore clustering in machine learning, focusing on k-means and hierarchical algorithms. Learn to uncover data relationships and apply techniques with practical considerations.
Introduction to Python Libraries and Algorithms for Machine Learning
Explore Python libraries and algorithms for machine learning, covering regression, clustering, and classification using popular tools like Pandas.
Discovery in High Dimensions - 2008
Explore statistical methods for uncovering hidden structures in high-dimensional data from various fields, including genetics, astronomy, and consumer behavior.

Machine Learning Course for Beginners - Theory
Comprehensive introduction to machine learning theory, covering algorithms, neural networks, and computer vision topics through engaging whiteboard animations designed for beginners.

SMB Witness Service Design and Implementation in Samba 4.20
Delve into SMB Witness Service implementation in Samba 4.20, exploring rpcd_witness functionality, cluster node monitoring, and Windows client interactions within ctdb clusters.