How to Discover and Locate Kubernetes Cluster Problems Before Users - Alibaba's Approach
阿里巴巴通过自研KubeProbe工具实现大规模K8s集群问题的快速发现和定位,包括链路探测、定向巡检、系统增强等功能,提高集群稳定性和故障处理效率。
Forget Kubectl and Talk to Your Clusters: Using LLMs to Simplify Kubernetes Cluster Management
探索利用大语言模型简化Kubernetes集群管理,实现自然语言交互、提高操作效率、识别解决问题。分享实际经验、讨论能力局限,探讨在确定性环境中消除模型不确定性的方法。
Live CNI Migration in Production Environments
探讨容器网络接口(CNI)实时迁移的方法和挑战,包括基础知识、迁移需求、基本和改进的迁移方法,以及大规模集群迁移的经验教训。
The Positive Side of Pending Pods - A Toolkit for App Lifecycle
Explore the benefits of pending pods in Kubernetes, learn to manage and monitor them effectively, and discover tools for optimizing application lifecycle management in complex deployments.
SIG-Scheduling Introduction and Deep Dive
深入探讨Kubernetes调度器工作原理、定制化方法和大规模集群最佳实践。适合新手和资深用户,涵盖SIG-Scheduling最新进展。
What's New in Kubespray - SIG Cluster Lifecycle
Explore Kubespray's latest features: HA with kube-vip, offline deployment, multi-arch support, and more. Learn best practices, community insights, and future directions for this versatile Kubernetes cluster manager.
[Portuguese] Servindo 1MM de Mensagens Simultâneas com RabbitMQ - Usando Consul para Alta Resiliência
Aprenda a criar um RabbitMQ altamente resiliente usando Consul para processar até 200 mil mensagens por segundo. Explore problemas, soluções e evoluções para uma implementação robusta.
Getting Started with Apache Spark on Kubernetes
Learn to deploy and optimize Apache Spark on Kubernetes with hands-on demos, covering environment setup, application sizing, performance tuning, and monitoring for efficient data pipeline management.
Simplify and Boost Spark 3 Deployments with Hypervisor-Native Kubernetes
Explore integrating Spark 3 with VMware Pacific for scalable, reliable, and high-performance big data analytics deployments using hypervisor-native Kubernetes on vSphere 7.
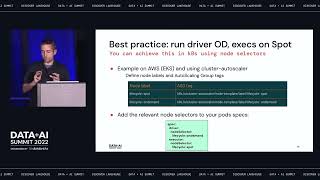
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Deploying Apache Spark Jobs on Kubernetes with Helm and Spark Operator
Learn to deploy Scala Spark jobs on Kubernetes using Helm and Spark Operator. Live coding demo shows scalable, flexible deployments with minimal custom configurations for stress-free implementation.
Managing Multi-Cloud Apache Spark on Kubernetes
Learn strategies for managing Apache Spark on Kubernetes across multiple clouds, focusing on auto-scaling, scheduling, and observability techniques for efficient data science infrastructure.
Rook: Introduction and Deep Dive with Ceph Storage - Kubernetes Cloud-Native Storage
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph for robust block, file system, and object storage in production environments.
Spark on Kubernetes: Building an Elastic Service - Apple's Approach
Explore Apache Spark on Kubernetes, focusing on autoscaling challenges and solutions for efficient large-scale data processing in multi-tenant environments with advanced features.
Dynamic Large Scale Spark on Kubernetes: Empowering the Community with Argo Workflows and Argo Events
Discover best practices for building scalable Spark clusters on Kubernetes using Argo Workflows and Argo Events, enabling efficient resource utilization and seamless scalability for powerful data processing.
Lightning-fast R and Python Library Loading for Databricks Clusters
Discover a productivity hack to load R packages and Python libraries in under 60 seconds when spinning up clusters, eliminating wait times and boosting efficiency in data science workflows.
Kepler - Powering Up the Efficiency of Your Cluster
Explore Kepler, a Kubernetes-based tool for measuring container energy consumption, enabling sustainable cluster management and optimized energy use through metrics and observability.
Strimzi Auto-rebalancing on Cluster Scaling - Feature Overview and Demo
Discover how to implement auto-rebalancing features in Strimzi 0.44.0 for efficient cluster scaling through a practical demonstration of problem-solving approaches and usage techniques.
Azure HDInsight Automation - PowerShell Meets Hadoop!
Automate Azure HDInsight for cost management and value maximization. Learn to create, call, and run functions, manage clusters, and leverage the Hadoop ecosystem efficiently.
Azure Databricks - A Brief Introduction
Explore Azure Databricks, a Big Data service based on Apache Spark. Learn about its features, security, and integration with Python, R, SQL, and machine learning frameworks.
InfluxDB + Telegraf Operator - Easy Kubernetes Monitoring
Explore easy Kubernetes monitoring using InfluxDB and Telegraf Operator. Learn efficient data collection, storage, and visualization techniques for enhanced cluster management.