Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
Create a Databricks Workspace - Lesson 2
Learn to create a Databricks workspace in Azure, understanding its components, pricing, and setup process. Gain practical skills for setting up your cloud-based data analytics environment.
Automating FAA's SWIM Data Ingestion and Analysis with Databricks
Automating FAA's SWIM data ingestion and analysis using cloud-based services, showcasing infrastructure setup, configuration, and insights derived from flight data for improved air transportation management.
Data Microservices in Apache Spark Using Apache Arrow Flight
Explore efficient machine learning pipelines using Apache Arrow Flight in Spark, enabling faster data transport and simplified microservices for improved ML model production.
Data Science Across Data Sources with Apache Arrow - Accelerating Analytics and Interoperability
Explore Apache Arrow's columnar in-memory data representation for real-time analytics across distributed systems. Learn how it accelerates data processing and enables interoperability between various analytical tools and data sources.
Building a Data Platform for Mission-Critical Analytics on AWS with Databricks
Explore building enterprise data lakes on AWS with Databricks, complementing AWS strategy. Learn from HP's success in transforming business through unified data analytics and overcoming data lake challenges.
Running Apache Spark on Kubernetes - Best Practices and Pitfalls
Learn best practices and pitfalls for running Apache Spark on Kubernetes, covering setup, performance optimization, resource management, security, and future developments in this comprehensive overview.
How to Build a Cloud Data Platform - Machine Learning and Business Intelligence - Part 4
Learn to leverage Delta Lake for dashboards and advanced analytics, enabling downstream teams with machine learning and business intelligence capabilities on a unified data platform.
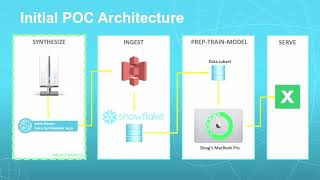
Securely Enabling Data Science in the Cloud
Explore secure cloud-based data science strategies, focusing on enabling analytics while maintaining data privacy and compliance across various cloud providers and data types.
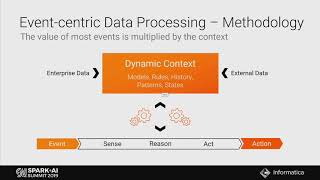
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
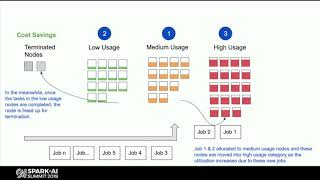
Downscaling Apache Spark Clusters - Challenges and Solutions
Explore techniques to improve downscaling in Spark-on-YARN clusters, addressing container fragmentation and shuffle data challenges for efficient resource management and faster autoscaling.
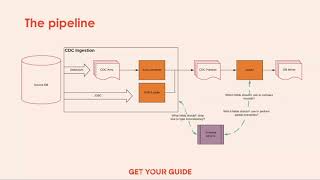
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.
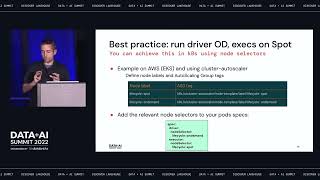
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Improving Apache Spark Application Processing Time - Configuration and Optimization Techniques
Optimize Spark streaming app performance through configurations, code improvements, and custom data source implementation for processing 700 MB/s of compressed data with strict KPIs.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
Securing Databricks on AWS Using PrivateLink - Deployment and Automation
Learn to secure Databricks on AWS using PrivateLink, covering architecture, setup, and automation. Gain insights on minimizing public internet data transfers for enhanced security and cost-efficiency.
The Azure Machine Learning Service - Introduction
Explore Azure ML Service's features for scaling, automating, and deploying machine learning pipelines. Learn how it enhances the data science process and addresses key challenges.

Jump Start on Data Science with an Azure Data Science VM
Learn to quickly set up and use an Azure Data Science Virtual Machine, equipped with essential tools for data science and machine learning projects.
Migrating Pinterest Apache Spark Clusters from HDFS to S3
Explore Pinterest's migration of Apache Spark clusters from HDFS to S3, addressing technical challenges, optimizing performance, and achieving a smooth transition process.
Deploying Apache Spark Jobs on Kubernetes with Helm and Spark Operator
Learn to deploy Scala Spark jobs on Kubernetes using Helm and Spark Operator. Live coding demo shows scalable, flexible deployments with minimal custom configurations for stress-free implementation.