Site Reliability Guardian (SRG) - Automating Change Impact Analysis for Service Reliability
Automate release validation and change impact analysis for service reliability with Dynatrace's Site Reliability Guardian app. Learn key use cases and see it in action.
Site Reliability Guardian (SRG) - Auto-Adaptive Thresholds for AI-Driven Quality Gating
Explore Dynatrace's Site Reliability Guardian update featuring auto-adaptive thresholds for AI-driven quality gating. Learn about internal adoption use cases and see a live demo.
Site Reliability Guardian (SRG) - October 2023 Update: Automating Change Impact Analysis
Explore Dynatrace's Site Reliability Guardian updates: templates, variables, and heatmap visualization for automated release validation and change impact analysis. Essential for SREs, DevSecOps, and Platform Engineers.
Kubernetes Cost Allocation Done Right
Explore Kubernetes cost allocation strategies, including visibility across workloads, showback/chargeback programs, and empowering users with actionable cost information.
How GitLab.com Uses Long-Term Monitoring Data for Capacity Forecasting
Explore GitLab's Tamland tool for capacity planning, leveraging long-term monitoring data and predictive forecasting to anticipate and address potential issues in large-scale service operations.
AI Augmentation in Finance - An Interplay Between Human and Machine
Explore AI augmentation in finance, enabling decision-makers to extract key insights from complex data for effective decision-making and trend identification.
System Performance and Queuing Theory - Concepts and Application
Explore queueing theory basics and its application to software systems. Learn to configure systems, predict performance, and identify breaking points using real-world data and metrics.

Scaling Game Technology and Engineering Teams - Challenges and Solutions
Experts discuss scaling game technology, engineering teams, and infrastructure. Insights on growth challenges, serverless architecture, microservices, and fostering curiosity in product development.
Capacity Constraints Unveiled: Navigating Cloud Scaling Realities
Explore cloud capacity challenges, solutions, and lessons learned from Elastic Cloud's growth experience. Gain insights into effective capacity planning for SREs in the face of scaling limitations.
Don't Be Greedy: Rightsize Your Kubernetes Cluster with Prometheus
Learn to optimize Kubernetes clusters by setting proper resource limits and requests. Discover techniques to identify unused resources, adjust container configurations, and measure optimizations for efficient cluster management.
Docker for SysAdmins: Deploying Containerized Workloads
Explore containerization for sysadmins: deployment considerations, security, capacity planning, and practical implementation strategies for Docker in enterprise environments.
Scaling Monitoring at Databricks - From Prometheus to M3
Learn how Databricks scaled their monitoring infrastructure from Prometheus to M3, exploring architecture, migration, lessons learned, and future plans for improved observability.
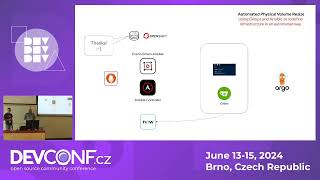
Enhancing Resilience in OpenShift Clusters with Ansible Event Driven Automation
Optimize OpenShift Data Foundation storage with real-time monitoring and dynamic capacity adjustment. Integrate backup restoration for rapid recovery and minimal downtime.
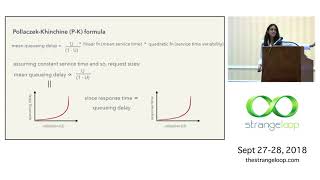
A Practical Look at Performance Theory
Explore performance theory for system tuning and capacity planning. Learn Little's Law, Universal Scalability Law, and real-world applications from companies like Facebook.
Exadata Warehouse - Simplify Capacity Planning and Forecasting for Exadata
Discover how Exadata warehouse simplifies capacity planning and forecasting, enabling long-term analysis, resource utilization insights, and accurate workload predictions for improved database management.
OpenShift Deep Dive - Running a Large, Public PaaS
Explore OpenShift Online's architecture, management, and evolution. Learn about application creation, maintenance, and scaling in Red Hat's public PaaS, with insights on enterprise deployment.
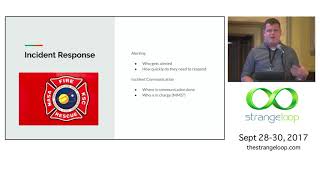
Practical Applications of the Dickerson Pyramid
Exploring real-world implementations of the Dickerson Pyramid for Site Reliability Engineering, with examples from Google, Hillary for America, and First Look Media.
SRE and DevOps at a Startup
Exploring SRE and DevOps implementation strategies for startups, comparing centralized and distributed team approaches, and discussing challenges and lessons learned.
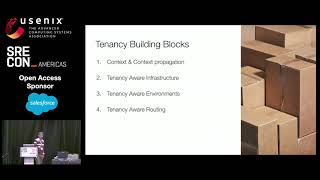
Testing in Production at Scale
Explore real-world insights on implementing testing in production for large-scale microservices, focusing on architecture, capacity planning, and infrastructure components.
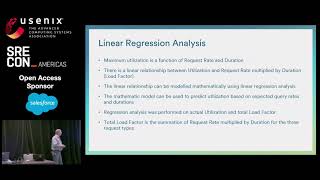
Capacity Prediction in External Services
Learn to predict resource exhaustion in external systems using linear regression, enabling proactive planning and sizing for improved application performance.
How to Do SRE When You Have No SRE
Practical strategies for implementing Site Reliability Engineering principles in resource-constrained environments, focusing on gradual improvements and stress reduction for engineering teams.