PySpark - Data Processing in Python on Top of Apache Spark
Learn PySpark for large-scale data processing with Python on Apache Spark. Covers RDDs, DataFrame API, transformations, actions, and data sources. Ideal for those seeking efficient big data analysis techniques.
Beyond the Basics with Elasticsearch
Explore advanced Elasticsearch scenarios: trend detection using aggregation framework, percolator for reversed search, and geo-enabled search with relevancy for non-trivial data analysis.
New Trends in Storing Large Data Silos with Python
Explore emerging technologies for handling Big Data in Python, focusing on efficient storage solutions and leveraging modern architectures, with insights on future trends and practical examples.
What's the Fuzz All About - Randomized Data Generation for Robust Unit Testing
Explore randomized data generation for robust unit testing using the Hypothesis library in Python, enhancing test coverage and detecting potential bugs through dynamic testing approaches.
Is That Spam in My Ham?
Learn to build a basic spam classifier using Python and Naive Bayes. Explore key machine learning concepts, implement a model to detect spam emails, and understand how to measure and improve classification performance.
Hyperconvergence Meets BigData
Explore deploying Wendelin, a Big Data & Machine Learning platform, using SlapOS, a hyperconverged OS. Learn to create and manage a complete Big Data infrastructure with Python-based tools.
What is the Best Full Text Search Engine for Python?
Explore and compare full text search engines for Python, including ElasticSearch, Postgres Full Text Search, Sphinx, and Whoosh. Gain insights on performance, features, and selection criteria.
SQLAlchemy as the Backbone of a Data Science Company
Explore SQLAlchemy's advanced features for data science, including Core API, Expression Language, and database migrations. Learn to scale relational models for handling billions of records efficiently.
Log All the Things!
Discover how to collect, clean, store, and analyze log data from various systems using the ELK stack, enhancing DevOps practices and gaining valuable insights into your infrastructure.
Realtime Distributed Computing at Scale - Storm and Streamparse
Explore realtime distributed computing using Apache Storm and streamparse in Python. Learn to handle high-volume data processing with low latency and high availability, suitable for large-scale production environments.
Inside Airbnb - Visualizing Data That Includes Geographic Locations
Aprende a visualizar datos geográficos utilizando herramientas como Bokeh, Holoviews y Datashader. Explora técnicas para representar información de Airbnb en mapas interactivos y dashboards dinámicos.
Using Pandas and Dask to Work with Large Columnar Datasets in Apache Parquet
Explore efficient techniques for handling large columnar datasets using Pandas and Dask with Apache Parquet, including partitioning, row group skipping, and optimized data layout for faster queries.
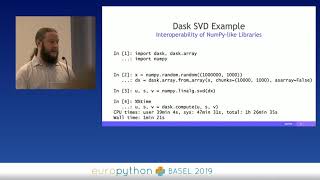
Distributed Multi-GPU Computing with Dask, CuPy and RAPIDS
Explore distributed multi-GPU computing using Dask, CuPy, and RAPIDS. Learn to leverage GPU acceleration and distributed systems for faster, more efficient data processing and analysis.
Building Data Workflows with Luigi and Kubernetes
Learn to build complex data pipelines using Luigi, package them as Docker images, and deploy on Kubernetes for scalable Big Data workflows with on-demand scaling and cost reduction.
Real Time Stream Processing for Machine Learning at Massive Scale
Practical insights on building scalable data streaming ML pipelines for real-time processing using Python, Kafka, SpaCy, and Seldon. Covers key concepts and best practices through a Reddit comment moderation case study.
NLPeasy - A Workflow to Analyse, Enrich, and Explore Textual Data
Discover NLPeasy: a streamlined workflow for analyzing, enriching, and exploring textual data using pre-trained models, Docker, and Jupyter Notebooks. Simplify your NLP projects with this powerful Python package.
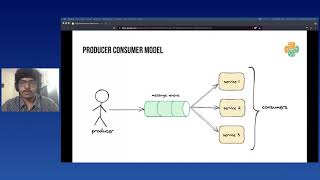
High Performance Data Processing with Python, Kafka and Elasticsearch
Explore high-performance data processing using Python, Kafka, and Elasticsearch. Learn to implement a Producer-Consumer model for real-time data updates in various applications.
Choosing the Right Database for Your Next Project - Looking at Options Beyond PostgreSQL and MySQL
Explore diverse database options beyond PostgreSQL and MySQL, covering relational, data warehouse, analytics, and machine learning solutions to find the best fit for your Python project.
Fish and Chips and Apache Kafka
Learn Apache Kafka® basics through a British fish and chips shop model. Explore key concepts, multiple producers/consumers, and scalable message handling in this fun and practical introduction to data streaming.
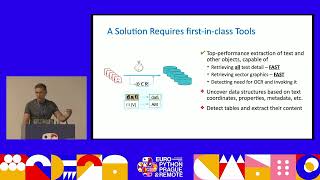
High Volume PDF Text Extraction Using Python Open-Source Tools
Learn efficient techniques for extracting text from large volumes of PDF documents using Python open-source tools, focusing on speed, OCR integration, and detailed information retrieval for business insights.
Apache Spark vs Cloud-Native SQL Engines
Opinionated comparison of Apache Spark and cloud-native SQL engines, exploring their strengths, use cases, and complementary nature for data processing and business intelligence tasks.