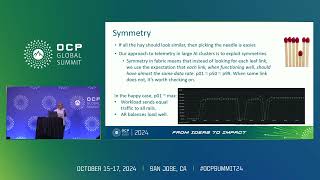
New Approaches to Network Telemetry for AI Performance Optimization
Discover innovative telemetry approaches for optimizing large-scale ML clusters, focusing on workload symmetries and performance metrics specific to AI infrastructure deployment.
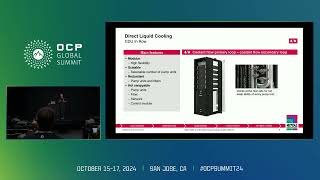
Modular OCP-based Direct Liquid Cooling Infrastructure for Future AI Applications
Explore innovative direct liquid cooling solutions for AI data centers, featuring modular OCP-based designs that optimize performance through advanced LTA and LTL cooling systems.
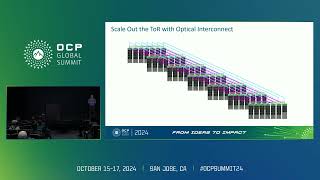
The Art of AI Networking Scaling to Support 100K GPU Nodes
Explore advanced networking technologies and solutions for scaling AI infrastructure to support massive GPU node deployments, focusing on optics, power, cooling, and management challenges.
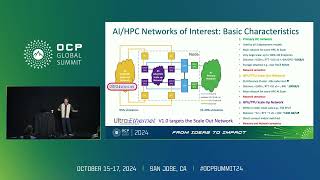
Ultra Ethernet Overview for AI and HPC Workloads
Discover how Ultra Ethernet technology enhances AI and HPC workloads, exploring its current state and key advantages for high-performance computing environments.
Enabling Chiplet Interoperability and Breakthroughs in AI
Explore how AMBA CHI C2C protocol enables seamless chiplet connectivity and acceleration for AI systems, focusing on Arm and NVIDIA's collaborative developments in chip-to-chip communication.
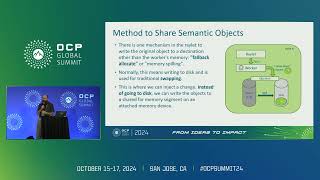
DIMSUM: Diving into Multihost Shared and Unified Memory
Explore modern AI's data challenges and how multi-host shared memory devices can revolutionize datacenter architecture, reduce costs, and optimize memory usage for large-scale AI workloads.
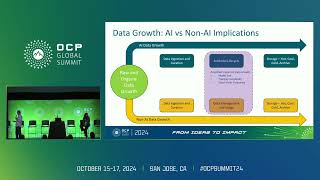
Storage Infrastructure and Architecture Design for AI Workloads
Explore how AI workloads are reshaping storage infrastructure requirements, from data acquisition to training, and discover emerging patterns influencing future storage architectures.
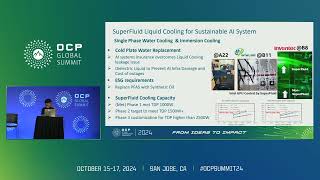
Accelerating Sustainable GenAI Computing Industry Adoption and Deployment
Explore OPEA's framework for sustainable GenAI computing, focusing on carbon-optimized solutions and ecosystem collaboration to address energy efficiency in large-scale AI deployments.
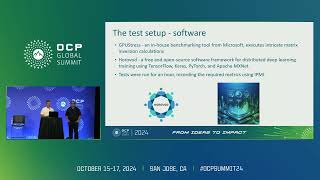
Combined Performance Metric for Data Center Efficiency in the AI Era
Explore a new data center efficiency metric (CPM) that combines GPU performance and power usage, designed specifically for evaluating AI workload infrastructure optimization.
Sustainable Strategies for Data Centers in the AI Era
Discover practical approaches to reduce data center carbon footprints through hydrogen power and transparent carbon reporting, as industry leaders share experiences and strategies for sustainable AI infrastructure.
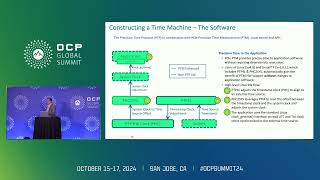
Improving AI Workload Efficiency Through Precise Time Synchronization
Discover how precision time synchronization can boost AI workload efficiency, reduce system idle time, and enhance datacenter performance through IEEE1588 and PCIe PTM technologies.
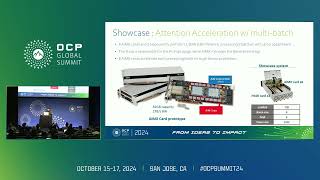
LLM Service Revolution Through Memory Computing Fusion Technology - From Datacenter to On-Device AI
Discover how SK Hynix's AiM technology revolutionizes LLM services through processing-in-memory solutions, offering enhanced efficiency and reduced costs for both datacenter and device-level AI applications.
Machine Learning Software Ecosystems: Frameworks, Compilers, and Models - Part 1
Explore the landscape of ML frameworks, compilers, and models while understanding performance considerations for various hardware platforms and edge computing requirements.
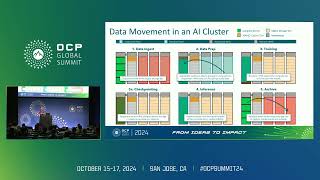
Optimizing High Density Storage for AI and ML Applications
Discover how to optimize high-density storage systems for AI/ML workloads, focusing on data pipelines, GPU utilization, and efficient solid-state storage solutions for large-scale models.
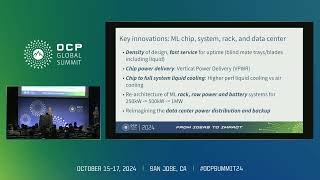
The Exponential Demands AI Places on the Rack and Datacenter
Explore how AI's growing computational demands reshape datacenter architecture, power requirements, and cooling solutions, with insights from NVIDIA and Google experts on future scaling challenges.
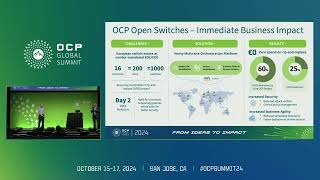
Automating the Migration Journey to Open Standards Networks
Discover how to automate network migration from proprietary to open-standards hardware, reducing downtime by 70% and costs by 60% while maintaining operational continuity and avoiding vendor lock-in.
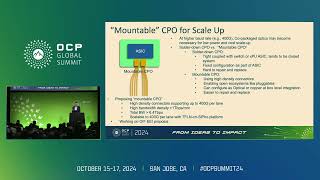
Energy-Efficient High Bandwidth Optical Interconnect Solutions for Generative AI
Explore cutting-edge optical interconnect technologies powering next-gen AI computing, from 800G deployment to 3.2T planning, focusing on power efficiency innovations like LPO, LRO, and CPO solutions.
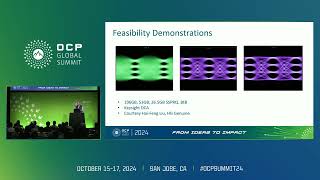
Implementing PCIe Connectivity with Optics - Optical Solutions for High-Speed Computing
Explore the latest developments in optical PCIe connectivity, focusing on protocol adaptations, new form factors, and enhanced link management for AI and high-performance computing applications.
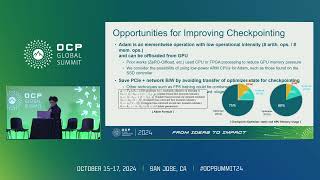
Checkpoint Offloading SSD - Enhancing Performance and Scalability in LLM Training
Discover how checkpoint offloading SSD technology optimizes LLM training by reducing GPU memory usage and improving data movement efficiency between storage components.
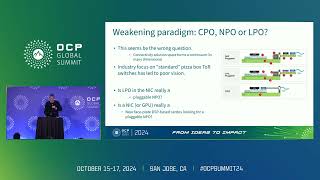
Linear Optics for AI Fabric Scale-Up and Scale-Out
Explore the role of linear optics in scaling AI infrastructure, focusing on both vertical and horizontal expansion strategies for enhanced system performance and connectivity.
Efficient Datacenter Scale AI Acceleration Using 3D Optics - Reducing Costs and Power Consumption
Discover how 3D optics revolutionizes AI acceleration in datacenters, offering enhanced performance while reducing costs and environmental impact through innovative optical computing solutions.