Enhancing Flexibility and Productivity with Access Patterns and Storage-Agnostic Abstractions
Explore a platform bridging data management gaps, offering storage-agnostic abstractions and ACID guarantees across streaming, batch, and random-access storages for flexible, consistent data handling.
Learning the Basics of Apache NiFi for IoT
Explore Apache NiFi for IoT data ingestion, processing, and visualization. Learn key features, workflows, and practical applications through demos and real-world examples.
Data Stream Processing - Concepts and Implementations
Explore data stream processing concepts, including time handling, Dataflow API, stream-table duality, data lookup, and deployment strategies. Compare implementations in Apache Spark Streaming, Flink, and Kafka Streams.
Real World Use Cases for Tachyon - A Memory-Centric Distributed Storage System
Explore Tachyon, a memory-centric distributed storage system for fast big data processing. Learn about its architecture, features, and real-world applications in various industries.
Zero Code Systems - Hopes, Myths and Reality
Explore low-code systems, their potential and limitations in business contexts. Learn from real-world experiences and discover innovative approaches to streamline development processes.

Introduction to Stateful Stream Processing with Apache Flink
Explore Apache Flink's advanced stream processing capabilities, including stateful computations, consistency guarantees, and high-performance data handling for real-time applications.
Unveiling Much Simplified Functional Programming in Scala for Data Engineering
Simplified functional programming in Scala for data engineering, focusing on feature generation abstraction and optimization techniques without complex libraries or boilerplate code.
Introduction to Stream Processing with Apache Flink
Explore Apache Flink's powerful stream processing capabilities, from basic concepts to advanced features. Learn how industry leaders leverage Flink for resilient, scalable data pipelines and stateful applications.
Why Spring Belongs in Your Data Stream - From Edge to Multi Cloud
Explore building data streaming apps at scale using Spring, from edge to multi-cloud. Learn to integrate Spring with Kafka, MQTT, and other technologies for real-time processing in IoT and cloud environments.
Real-Time Object Detection with Pravega and Flink
Explore real-time object detection using Pravega and Apache Flink, leveraging Dell EMC Streaming Data Platform and ObjectScale for enterprise-grade streaming and storage on VMware Cloud Foundation.
How Apache Beam Makes Your Data Processing Go
Explore Apache Beam's Go SDK for efficient distributed data processing, overcoming Go's unique challenges using reflection, interfaces, and generics for scalable pipeline execution.
Automated Translation of Functional Big Data Queries to SQL
Explore automated translation of functional big data queries to SQL, improving efficiency while maintaining abstraction benefits. Learn about novel column-wise decomposition for query synthesis.
Building Modern Data Streaming Apps with Python
Explore modern data streaming app development using Python, focusing on key benefits and unique aspects of building efficient, scalable applications.
FLiPN Stack for Edge AI - Flink, NiFi, Pulsar
Explore FLiPN Stack for Edge AI: Learn about Flink, NiFi, and Pulsar integration for efficient data processing and streaming in IoT environments.
Adding Generative AI to Real-Time Streaming Pipelines - Conf42 LLMs 2024
Explore integrating generative AI into real-time streaming pipelines, covering enterprise use cases, model selection, and implementation using tools like NiFi, Flink SQL, and cloud services.
Is Contributing to Open Source Difficult? - Overcoming Barriers and Achieving Success
Discover strategies to overcome barriers and balance work with open-source contributions, drawing from real experiences in the Apache community.
Building a Kubernetes Operator for Apache Flink in Java
Develop Kubernetes Operators in Java for complex applications like Apache Flink. Learn implementation basics, advantages of Java Operator SDK, and insights from large-scale production use-cases.
3 Flink Mistakes We Made So You Won't Have To
Discover key lessons and avoid common pitfalls when adopting Apache Flink for stream processing. Learn to optimize Kafka integration, memory configuration, and checkpointing for efficient and reliable data processing.

How to Use Streaming Joins with Apache Flink
Explore streaming joins in Apache Flink®, covering stateless, materializing, and temporal operations. Learn through demos on updating, appending, and versioned table joins for effective data combination.
Event-Driven Architectures: Fundamentals and Advanced Concepts
Explore event-driven architectures, including event immutability, windowing techniques, and practical applications in Apache Kafka and Flink ecosystems. Gain insights from industry experts in an engaging Q&A format.
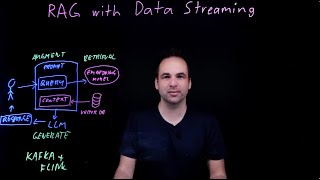
Retrieval Augmented Generation (RAG) with Data Streaming for GenAI Applications
Explore Retrieval Augmented Generation (RAG) with data streaming to enhance LLM outputs. Learn how Apache Kafka and Flink enable real-time, contextualized data for reliable GenAI applications.