Generate Test Data Quick, Easy and in Large Volumes with the Databricks Labs Data Generator
Generate terabytes of proper test data quickly and easily using Databricks Labs Data Generator for dev environments across Azure, AWS, and GCP.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.
Build, Train, and Deploy Models with Amazon SageMaker
Learn to build, train, and deploy machine learning models using Amazon SageMaker through hands-on experience. Gain practical skills in ML model development and implementation on AWS platform.
Serverless for Machine Learning Pipelines
Explore serverless architecture for ML/DL deployment, utilizing AWS services to organize scalable and affordable deep learning workflows for efficient model training and operationalization.
The Value Flywheel Effect: A Modern Cloud Strategy - Interview with David Anderson
Explore serverless-first strategies, Wardley Mapping, and the Value Flywheel Effect for modern cloud transformation. Learn to align business and IT, foster psychological safety, and drive rapid software development.
Databricks MLOps: Accessing Data with Dbutils FS in Azure, AWS, and GCP
Learn to access data using Dbutils FS in Azure, AWS, and GCP for Databricks MLOps. Master essential techniques for efficient data handling in cloud environments.
Bringing LAMBDA to Excel
Explore the journey of integrating functional programming into Excel, showcasing new capabilities and future research directions in spreadsheet technology.
How to Use LAMBDA: Create New Formulas in Excel
Master LAMBDA functions in Excel to create custom, reusable formulas tailored to your specific needs. Learn to define variables, structure formulas, and enhance workflow efficiency.
Genomic-scale Data Pipelines - Building Serverless Bioinformatics Cloud Solutions
Explore genomic-scale data pipelines with cloud architects Lynn Langit and Denis Bauer. Learn about serverless bioinformatics, MedTech solutions, and cutting-edge approaches to handling large-scale genomic data.
Scaling LLM Inference - AWS Inferentia Meets Ray Serve on EKS
Discover how to build scalable, cost-effective LLM inference infrastructure using Ray Serve and AWS Inferentia on Amazon EKS, optimizing deployment of models like Llama2 and Mistral-7B.
Testing S3 Implementations - RGW and Beyond: Client and Server Perspectives
Explore S3 implementation testing methodologies, focusing on RGW compatibility, client-server perspectives, and validation techniques for ensuring spec compliance and optimal performance.
AWS EMR Demystified - Part 4
Master AWS EMR's core components, from networking and storage to running PySpark jobs, while exploring integration with AWS Glue and Athena for effective big data processing and transformation.
AWS EMR Demystified - Part 3
Master AWS EMR's integration with Glue, Athena, and PySpark while learning essential data transformation techniques and architectural considerations for optimizing your data lake implementation.
AWS EMR, Hadoop, and Data Lake Architecture - Part 2
Master AWS EMR's core components, including networking, storage types, and integration with AWS Glue and Athena. Learn to execute PySpark jobs and understand data transformation challenges in EMR-based data lakes.

Cloud Object Storage: Evolution, Architecture, and Implementation - From S3 to Modern Solutions
Explore the evolution, architecture, and technical implementation of cloud object storage, from Amazon S3's revolutionary beginnings to modern implementations like Backblaze B2.
ACID Complexity in Modern Databases - Understanding Transaction Evolution and Implementation
Explore the evolution and complexities of database transactions, from fundamental ACID properties to modern distributed systems like Aurora, DynamoDB, and Spanner.

Beyond S3 Compatibility Claims: A Deep Dive into Real-World Incompatibilities
Dive into real-world S3 API compatibility challenges, exploring common incompatibilities, implementation hurdles, and practical solutions for developing robust object storage systems that align with industry standards.
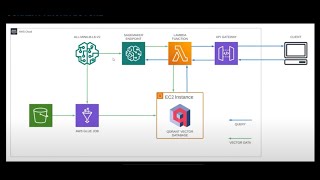
High-Performance Entity Matching Solution Using Vector Embeddings and AWS
Discover how to build a high-performance hotel matching system using vector embeddings, AWS infrastructure, and Qdrant for efficient data processing and improved accuracy in the travel industry.
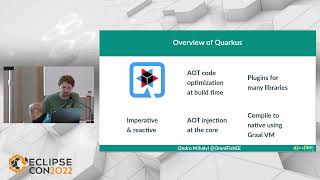
Java Cold Starts in Serverless: Performance Optimization with Modern Frameworks
Explore Java's true performance in serverless environments, debunking cold start myths while mastering optimization techniques for AWS Lambda using modern frameworks like Quarkus and Piranha Cloud.

How to Schedule and Automatically Run Python Code
Learn to automate Python scripts locally and in the cloud using cronjobs, Windows Task Scheduler, AWS Lambda, and Cloudwatch. Includes practical examples for scheduling email sending and generating analytics reports.
ECS and EKS - What Works Best for Your Project? - AWS ECS vs EKS
Comprehensive comparison of AWS ECS and EKS, exploring features, differences, and use cases to help choose the right container management solution for your project.