Machine Learning Applications
Explore text mining applications in machine learning, covering techniques, challenges, transformations, and model building using logistic regression and TF-IDF for practical implementation.
Natural Language Processing
Explore natural language processing (NLP) concepts, review Text preprocessing and data cleaning, learn forward propagation and back propagation in neural networks, Word Embedding using Keras and deep learning with examples
Text Analytics Crash Course with R
Learn text analytics fundamentals, data processing, machine learning models, and visualization techniques using R. Master handling big data and optimizing models for valuable insights from unstructured text.
SPLADE - The First Search Model to Beat BM25
Explore SPLADE, a groundbreaking sparse embedding model for AI-powered search. Learn its advantages over traditional methods, implementation techniques, and potential future developments in vector search technology.
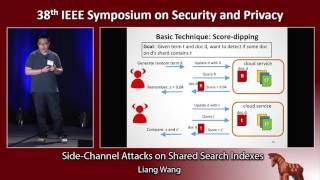
Side-Channel Attacks on Shared Search Indexes
Explore side-channel attacks on shared search indexes, uncovering vulnerabilities in multi-tenant systems. Learn about STRESS attack techniques and their implications for popular services.
Introduction to Text Analytics with R - Pre-Processing Our Test Data
Learn to preprocess test data, cache IDF values, perform SVD projections, and evaluate model effectiveness for text analytics in R. Enhance your skills in handling unseen textual data and making predictions.

N-Grams - Introduction to Text Analytics with R
Explore N-grams in text analytics, including TF-IDF validation, word ordering, dimensionality challenges, and hardware limitations. Enhance your R-based text analysis skills.

TF-IDF - Introduction to Text Analytics with R
Explore TF-IDF for text analytics in R: improve document representation, handle unequal lengths and common terms, implement TF-IDF, and clean data matrices post-weighting.
Singular Value Decomposition with R - Introduction to Text Analytics with R Part 8
Learn to perform truncated SVD, project TF-IDF vectors into semantic space, compare decision tree and random forest models, and explore random forest tuning using R packages like irlba and caret for text analytics.
Improving RAG Pipelines with Contextual Information Retrieval
Master advanced RAG techniques by exploring hybrid approaches combining semantic embeddings with TF-IDF and BM25, plus learn about Anthropic's Contextual Retrieval method for enhanced performance.
From Documents to Vectors: Understanding ChatGPT's Technical Architecture with OpenAI Plugins
Dive into the technical architecture of ChatGPT plugins, exploring vector databases, API endpoints, and real-time data retrieval methods for enhanced AI capabilities.
Topic Modeling with R and Tidy Data Principles
Explore topic modeling in R using tidytext and stm packages, applied to Sherlock Holmes stories. Learn data preparation, text tidying, and model implementation techniques.
Vector-Based Methods for Similarity Search - TF-IDF, BM25, SBERT
Explore three vector-based approaches for language comparison and document similarity: TF-IDF, BM25, and Sentence-BERT. Learn key techniques for building effective search engines in AI and machine learning.
Building a Naive Bayes Text Classifier with scikit-learn
Learn to build a Naive Bayes text classifier using scikit-learn, exploring preprocessing techniques and feature extraction methods for effective spam detection in YouTube comments.
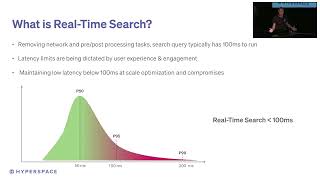
Breaking Search Performance Limits with Domain-Specific Computing
Explore advanced search techniques using domain-specific computing to achieve faster latencies and higher scalability at billion-scale, overcoming limitations of general-purpose CPUs.
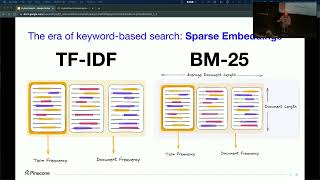
Better Semantic Search with Hybrid Sparse-Dense Search - Haystack US 2023
Explore hybrid search techniques combining sparse and dense embedding models to enhance semantic search accuracy and effectiveness in various scenarios.
Vector and Hybrid Search with Elasticsearch
Explore vector and hybrid search in Elasticsearch, covering classic search limitations, models, implementation, and integration with LLMs like ChatGPT for enhanced data retrieval.
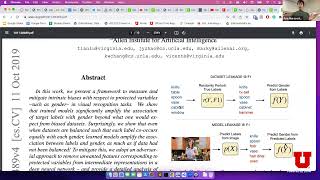
Data Mining: Embeddings and Representations in Machine Learning - Spring 2023
Explore data representation techniques from TF-IDF to contextualized embeddings, covering word analogies, societal biases, and image representations for advanced data mining applications.

Black Hat USA 2025
Black Hat USA 2025