LLMOps: Como usar Nvidia TensorRT SDK para Inferencia en GPU
Optimiza la inferencia en GPU con Nvidia TensorRT SDK, convirtiendo modelos y comparando tiempos de ejecución en diferentes precisiones de datos.
LLMOps: Comparación de Openvino, ONNX, TensorRT y Pytorch para Inferencia
Compara el rendimiento de inferencia de modelos convertidos a ONNX, OpenVino y TensorRT frente a PyTorch nativo en GPU y CPU.
NVIDIA Jetson: Enabling AI-Powered Autonomous Machines at Scale
Explore NVIDIA Jetson's AI platform for edge computing in robotics, healthcare, and more. Learn about hardware, software stack, ecosystem, and real-world applications.
Embedded Deep Learning with NVIDIA Jetson
Learn to develop AI and computer vision applications using NVIDIA's deep learning tools. Explore neural network primitives, real-time solutions, and training workflows for intelligent robots and drones on the Jetson Embedded Platform.
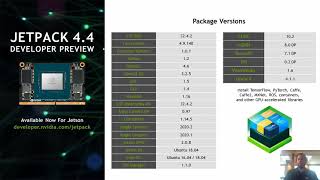
Jetson Xavier NX Developer Kit - Edge AI Supercomputer Features and Applications
Explore Jetson Xavier NX Developer Kit's edge AI capabilities, software features, and deployment strategies for advanced applications in video analytics, perception, and natural language processing.
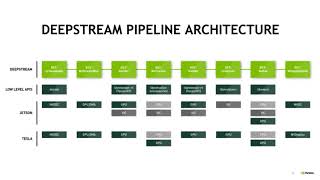
Streamline Deep Learning for Video Analytics with DeepStream SDK 2.0
Explore AI-based video analytics using DeepStream SDK 2.0 for Tesla, transforming video into insights for smart cities with a modular plugin architecture and scalable framework for multi-stream processing and application development.
Inference and Quantization for AI - Session 3
Explore quantized inference, TensorRT 5, and TensorFlow integration for AI model optimization. Learn about NVIDIA's inference server and techniques to improve model efficiency and performance.
Doubling Stable Diffusion Inference Speed with RTX Acceleration and TensorRT - A Comprehensive Guide
Comprehensive guide on boosting Stable Diffusion performance with RTX Acceleration TensorRT, covering installation, optimization, and troubleshooting for various models and extensions.
LLMOps: Comparison of OpenVino, ONNX, TensorRT, and PyTorch Inference
Explore model conversion to ONNX, OpenVino, and Tensor-RT formats for optimized CPU and GPU inference, comparing performance against native PyTorch.
LLMOps: Using Nvidia TensorRT SDK for GPU Inference
Optimize GPU inference using Nvidia TensorRT SDK. Convert models, compare throughput, and explore batch sizes, data precision, and runtime options for enhanced performance.
Building Qrio, a Bot That Plays Videos for My Toddler
Discover how to build an AI bot that interacts with toddlers, recognizes toys, and plays relevant YouTube Kids videos. Learn about object detection, text-to-speech, animation, and automation techniques.
Speed-ups for State-of-the-Art Generative AI Drug Discovery Applications
Explore cutting-edge generative AI techniques for drug discovery, including VAEs, Hugging Face pipelines, and LLM comparisons. Learn to accelerate inference times using C++ and cloud platforms.

Deploying Deep Learning Models for Inference at Production Scale
Optimize and deploy AI models at scale using NVIDIA TensorRT and Triton Inference Server. Learn production-ready techniques for efficient inference across various platforms and infrastructures.
EfficientML.ai - Quantization Part II - Lecture 6
Explore advanced quantization techniques for efficient machine learning, including post-training and quantization-aware training methods.
EfficientML.ai: Quantization Part II - Lecture 6
Explore advanced quantization techniques for efficient machine learning, covering post-training and quantization-aware training methods to optimize model performance.