
Python Web Scraping and Crawling Using Scrapy
Learn web scraping and crawling with Scrapy, covering project setup, data extraction, storage in databases, pagination handling, login automation, and bypassing restrictions on various websites.

Python Web Scraping Tutorial
Learn to extract data from websites using Python, BeautifulSoup, and Scrapy. Master HTML parsing, error handling, and site crawling techniques for efficient web scraping projects.
Web Scraping With Scrapy
Learn to extract web data efficiently using Scrapy, covering setup, spider creation, HTML parsing, CSS selectors, and practical challenges for real-world applications.
Scrapy Tutorials
Learn to extract, process, and store web data efficiently using Scrapy. Covers basic to advanced techniques, real-world projects, and best practices for web scraping.
Scrapy for Beginners
Learn powerful web scraping with Scrapy: master selectors, spiders, and data extraction techniques. Ideal for beginners seeking to automate data collection from websites efficiently.
Tutorial: Web Scraping
Aprende técnicas de Web Scraping con Python, desde lo básico hasta lo avanzado, utilizando Scrapy, Beautiful Soup y Selenium para extraer datos de sitios web de manera eficiente.
Scrapy 爬蟲教學
學習使用Scrapy框架進行網頁爬蟲,從基礎概念到實際應用,包括抓取新聞、處理數據、存儲到數據庫,以及多網頁爬取和任務管理。
LLama 2 and PEFT Documentation - Building Interactive LLM with Retrieval Augmented Generation
Master building a RAG-enhanced LLM system using Llama 2 through hands-on coding. Learn web scraping, embedding generation, vector indexing, and semantic search to create an AI that leverages external knowledge sources.
Querido Diario - Cómo Liberar Datos Oficiales de Ciudades Brasileñas con Py
Proyecto para hacer accesibles los Diarios Oficiales de ciudades brasileñas mediante scraping, OCR y una API abierta, facilitando la búsqueda y análisis de datos gubernamentales.
Web Scraping in Python 101
Learn web scraping in Python: techniques, libraries, and best practices. Explore BeautifulSoup, lxml, and Scrapy for efficient data extraction from websites.
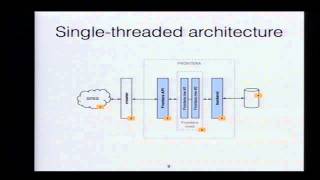
Frontera - Open Source Large-Scale Web Crawling Framework
Introduction to Frontera, an open-source framework for building large-scale web crawlers. Learn about its features, architecture, and how to create distributed crawlers using Scrapy, Kafka, and HBase.
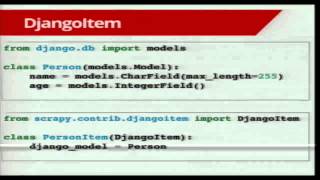
Dive into Scrapy
Explore advanced Scrapy techniques for web scraping, including project structure, interactive shell, item handling, and deployment strategies. Learn to avoid bans and optimize data extraction.
Data-Visualisation with Python and Javascript - Crafting a Data-Viz Toolchain for the Web
Explore data visualization using Python and JavaScript, from scraping and cleaning data to creating engaging web visualizations with tools like Scrapy, Pandas, Flask, and D3.js.

Live-Coding: Master Anti-Ban and Web Scraping with Scrapoxy
Master web scraping techniques and anti-ban strategies using Scrapoxy, Scrapy, and Playwright. Learn proxy handling, code deobfuscation, and effective methods to bypass anti-bot systems.

Ultimate Web Scraping Tutorial - From HTML Collection to Advanced Libraries
Master essential web scraping techniques using Python libraries like BeautifulSoup, Selenium, and Scrapy to efficiently collect and process data from websites while following best practices and security guidelines.