Privatsphäreschonende Gesundheitsdatenverarbeitung
Erfahre, wie Gesundheitsdaten für Forschungszwecke genutzt werden können, ohne die Privatsphäre zu verletzen. Entdecke innovative Ansätze zum Schutz sensibler Informationen im europäischen Gesundheitsdatenraum.
Understanding Probabilistic Data Structures with UFO Sightings
Explore probabilistic data structures through UFO sightings analysis. Learn about Bloom Filters, MinHash, and Top-K, and their applications in processing large datasets efficiently.
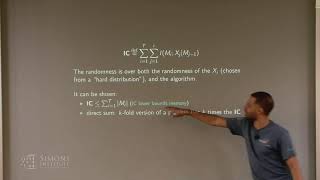
New Upper and Lower Bounds on Approximate Counting
Explores new upper and lower bounds for approximate counting, addressing amortized space complexity and memory optimization in maintaining arrays of approximate counters.
Probabilistic Data Structures
Explore efficient handling of large datasets using probabilistic data structures. Learn about their use cases, trade-offs, and implementation for improved performance and memory management.
Understanding Probabilistic Data Structures with UFO Sightings
Explore probabilistic data structures using UFO sighting data, learning efficient techniques for handling large datasets and extracting meaningful insights from seemingly random information.
Bootiful Multi-Model Applications with Redis Stack
Explore building Spring Boot applications with Redis Stack, leveraging multiple data models and functionalities including document store, graph database, time series, and full-text search.
No, Maybe and Close Enough - Using Probabilistic Data Structures in Python
Explore probabilistic data structures in Python for efficient counting and item recognition, focusing on Hyperloglog and Bloom Filter algorithms for fast, scalable solutions.
Understanding Probabilistic Data Structures with UFO Sightings
Explore probabilistic data structures using UFO sighting data. Learn about Bloom Filters, MinHash, and Top-K, and discover how these structures can efficiently process large datasets with trade-offs in precision.
Bootiful Multi Model Applications with Redis Stack
Explore building Spring Boot applications with Redis Stack, leveraging multiple data models and functionalities like document store, graph database, and full-text search through Redis OM Spring.
Hyper Speed! When Big Data Blooms
Explore high-speed data processing using Bloom Filters, a powerful probabilistic data structure. Learn to handle massive data volumes efficiently, with real-world examples and advanced techniques.
Understanding Probabilistic Data Structures with UFO Sightings
Explore probabilistic data structures using UFO sighting data. Learn about Bloom Filters, MinHash, and Top-K, and discover how these structures can efficiently process large datasets with a balance of speed and accuracy.
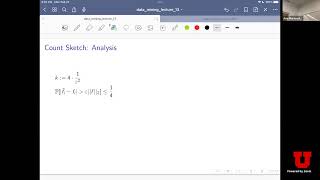
Data Mining: Count-Min Sketch and Count Sketch Algorithms - Spring 2023
Dive into advanced data mining techniques, focusing on Count-Min Sketch algorithms, space optimization, and comparative analysis with Misra-Gries method for efficient data processing.
Hyper Speed - When Big Data Blooms
Explore high-speed data processing techniques, including Bloom Filters, to handle massive volumes of telemetry data efficiently. Learn infrastructure strategies for processing 65,000 JSON payloads per second.
Count-min Sketch to Infinity - Using Probabilistic Data Structures to Solve Counting Problems in .NET
Explore probabilistic data structures like Count-Min Sketch, Bloom Filter, and HyperLogLog to efficiently solve counting problems in large-scale .NET applications.
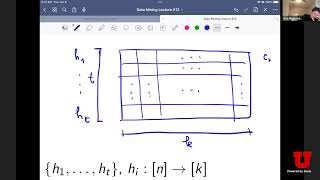
Data Mining: Sketch Algorithms and Count-Min Sketch Analysis - Spring 2023
Explore advanced sketch algorithms including Misra-Gries and Count-min techniques for efficient data mining, with detailed analysis and practical applications.