Integración de NVIDIA NIM con Langchain para RAG Q&A
Explora la integración de NVIDIA NIM con Langchain para crear un componente RAG Q&A utilizando Faiss, mejorando tus habilidades en inteligencia artificial y procesamiento de lenguaje natural.
NVIDIA NIM Integration with Langchain for RAG Q&A
Explore NVIDIA NIM integration with Langchain, creating a RAG Q&A system using Faiss for enhanced machine learning and data science applications.
Building RAG Applications with PDFs Using LlamaIndex - Comparing Gemini Pro and Nvidia NIM Llama 3.2
Master RAG implementation using LlamaIndex to create PDF-based conversational agents with Gemini Pro and Nvidia NIM Llama 3.2, leveraging PymuPDF for text and image extraction.
NVIDIA NIM: Deploying and Integrating Generative AI Models in Applications
Learn to deploy and integrate generative AI models using NVIDIA NIM. Explore vision and text models, create user interfaces, and implement image analysis and chat functionality in your applications.
RAG: Building Document Question-Answering with Nvidia NIM and LlamaIndex Integration
Descubre cómo implementar RAG utilizando LlamaIndex y Nvidia NIM para interactuar con documentos privados, integrando LLama 3.2 3B y Phi3 3.5 Small para procesamiento de lenguaje natural.
RAG Integration with Nvidia NIM and LlamaIndex - Building Document Query Applications
Explore building a RAG application using LlamaIndex and Nvidia NIM to effectively query private documents with LLama 3.2 3B and Phi3 3.5 Small 128k models.
Developing Local AI Copilots with LangChain, NVIDIA NIM, and FAISS - LLM App Development
Learn to build a local AI copilot using LangChain, NVIDIA NIM, and FAISS. Covers document processing, vector storage, inference with Llama 3, and LangChain orchestration for responsive LLM applications.
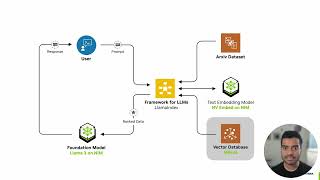
Building LLM Assistants with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to create a Q&A chatbot using NVIDIA NIM for embeddings, Milvus for storage, Llama3 for inference, and LlamaIndex for seamless integration in this comprehensive tutorial.
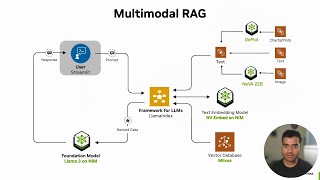
Building Multimodal AI RAG with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to build a multimodal AI RAG application using LlamaIndex, NVIDIA NIM, and Milvus. Covers document processing, vector database integration, inference with Llama 3, and seamless orchestration for efficient Q&A experiences.
Development and Deployment of Generative AI with NVIDIA
Discover how to rapidly develop and deploy enterprise-scale generative AI solutions using microservices, leveraging NVIDIA NIM and AI software for tailored business applications.
RAG - Extracting Information from PDFs Using LlamaIndex, Gemini, and Nvidia NIM with Llama 3.2
Aprende a extraer información de PDFs utilizando LlamaIndex, implementando modelos como Gemini y Nvidia NIM para embeddings junto con LLama 3.2 para procesamiento de lenguaje natural.
RAG: Nvidia NIM Integration with Langchain for HTML Web Page Parsing
Descubre cómo implementar aplicaciones RAG utilizando Langchain y Nvidia NIM para extraer información de páginas HTML, integrando el modelo Mistral 8 7b Instruct para procesamiento avanzado.
RAG - Parsing HTML Content with BeautifulSoup and Nvidia NIM Integration in LangChain
Dive into building RAG systems by integrating Nvidia NIM with LangChain, using BeautifulSoup for HTML parsing and Mistral 8 7b Instruct as the foundation model.
How to Pick a GPU and Inference Engine for Large Language Models
Explore GPU selection and inference engine optimization for large language models. Compare quantization effects, software options, and cost-efficiency across various GPUs and model sizes.
Building RAG Applications from Scratch with NVIDIA NIM Microservices
Dive into building scalable RAG applications using NVIDIA NIM microservices, covering text embedding, reranking, and chatbot integration for high-performance AI deployment.
Building a Conversational PDF Bot with LlamaIndex, Nvidia NIM, and Streamlit
Master building a conversational PDF bot using Streamlit, LlamaIndex, and Nvidia NIM to create interactive document-based chat applications with advanced RAG capabilities.