Cloud Agnostic Data Platform with DBT, Trino, Iceberg and MinIO
Explore a hands-on, cloud-agnostic data pipeline using TrinoDB, DBT, MinIO, and Apache Iceberg for scalable and lightweight analytics, suitable for both cloud and on-premise solutions.
Building an Object-based Storage as a Service Solution with Poseidon Storage
Discover how to build high-performance object-based Storage-as-a-Service solutions using Poseidon and Kubernetes, with insights into S3 performance benchmarking and ML workload optimization.
Building a Cloud Native Storage Service - Dropbox Example
Explore building a scalable, multi-tenant cloud storage system using containerized applications and Cloud Native architecture, with a live demo of a Dropbox-like product.
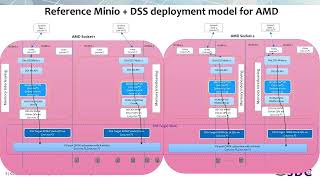
Evolving Storage Solutions for AI/ML Performance and Scale
Discover how Samsung's innovative object storage solutions and DSS stack optimize AI/ML workloads, enabling unprecedented performance and scalability for machine learning applications.
Exploring Vector Search at Scale with Milvus - Building Billion-Scale Solutions
Explore vector search at billion-scale through Milvus, understanding distributed systems architecture, indexing strategies, and scalability solutions for unstructured data processing.
Product Recommendation System on Kubernetes Using Argo Workflows
Learn to build a product recommendation system using Argo Workflows on Kubernetes. Explore DataOps, pipelines, and tools like Minio and Apache Spark for efficient data processing and analysis.
Writing Machine Learning Pipelines Against Object Storage
Learn to create efficient machine learning pipelines using object storage, optimizing data processing and model deployment for scalable AI solutions.
Introduction to KubeFlow: Using and Use Cases
Explore KubeFlow for machine learning on Kubernetes, covering components, use cases, and a practical recommender system example with collaborative filtering and TensorFlow.
Building Reproducible ML Processes with an Open Source Stack
Explore open-source tools for reproducible machine learning, covering code, data, and environment management. Includes hands-on demonstration of experiment replication using KubeFlow, Git, Minio, and lakeFS.
Deep Dive - Rook
Explore Rook's architecture, Kubernetes extension mechanisms, and cloud-native storage orchestration. Learn about controllers, operators, and automated storage solutions for Ceph, CockroachDB, Minio, and NFS.
The Fallacies of Distributed Computing
Explore fallacies of distributed computing in Go, examining real-world systems like Kubernetes and CockroachDB to address common misconceptions and challenges.
Why AI is All About Object Storage - Understanding Scale and Performance
Discover how object storage has become essential for AI architectures, offering superior performance, scalability, and simplicity for managing massive datasets and diverse data formats at enterprise scale.
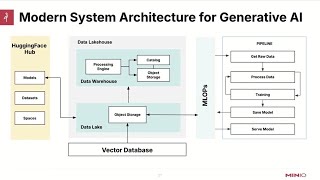
MinIO Enterprise Object Store: AI Features and RAG Deployment Demo
Explore MinIO's enterprise object store capabilities for AI workloads, featuring advanced observability, security, and performance tools for managing massive-scale data operations across cloud environments.
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.
How to Build a Cloud Native Data Lake with Open Source Technologies
Discover how to deploy a Kubernetes-based data lake using open source tools, from initial setup to running a complete prototype platform on your local machine.